

How to Extract Tables and Checkbox Data from PDFs in C#

Question details
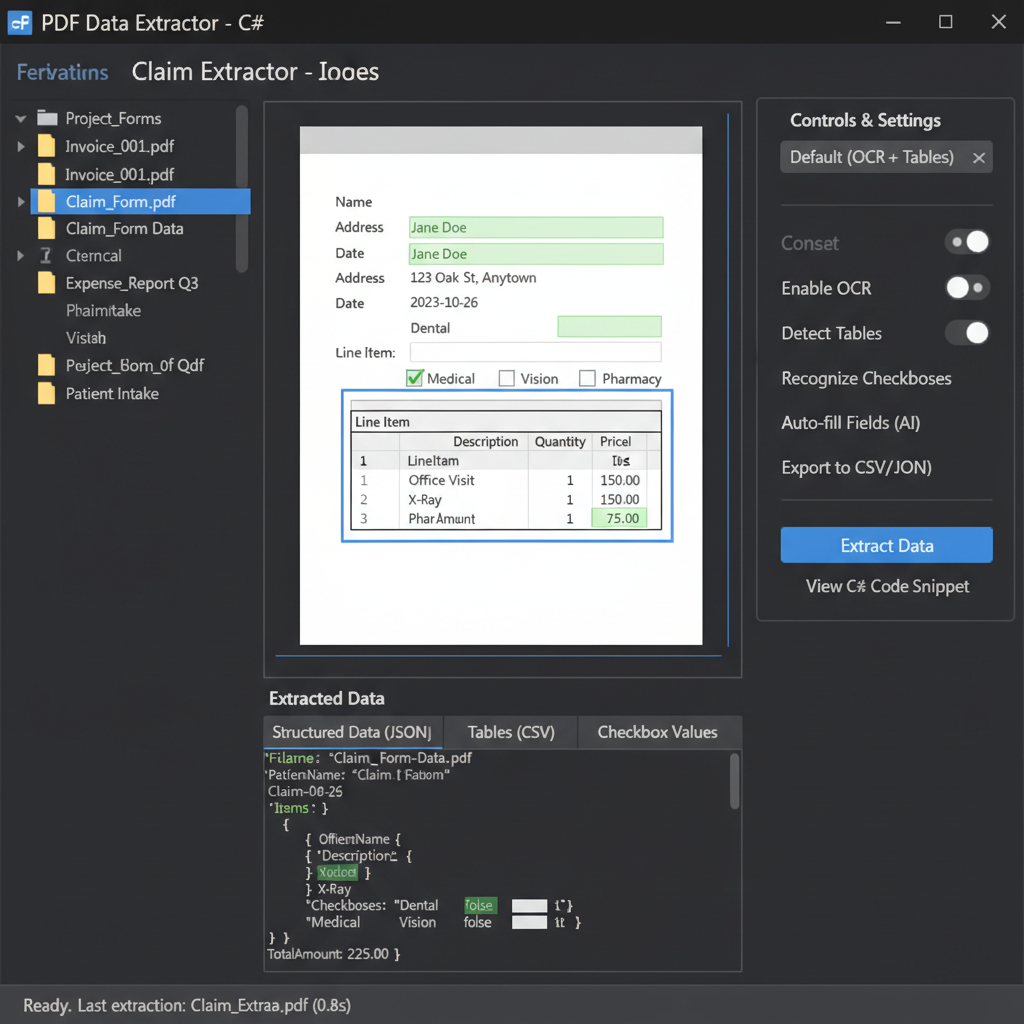
A developer needs a method to programmatically extract structured data, including tables, borders, and checkbox values, from various PDF forms using C#.
- Product
- C# PDF Extraction Libraries
- Device & OS
- not provided
- Scenario
- Automating data extraction from structured and unstructured PDF documents in a C# environment.
- Observed behavior
- The user is looking for capable libraries or APIs that accurately handle table recognition, OCR, and checkbox detection within PDF files.
Before writing your code, verify whether your source PDFs are native (text-searchable) or scanned (image-based), as scanned documents will require a library with Optical Character Recognition (OCR) capabilities.
Use a C# PDF Extraction Library
Integrate dedicated C# PDF parsing libraries like LEADTOOLS or Bytescout to handle complex table recognition and form field detection programmatically.
Specialized PDF SDKs provide built-in methods for identifying borders, parsing grid structures, and reading form fields. While open-source libraries exist, commercial libraries like LEADTOOLS and Bytescout often offer superior accuracy for unstructured tables and checkbox state detection.
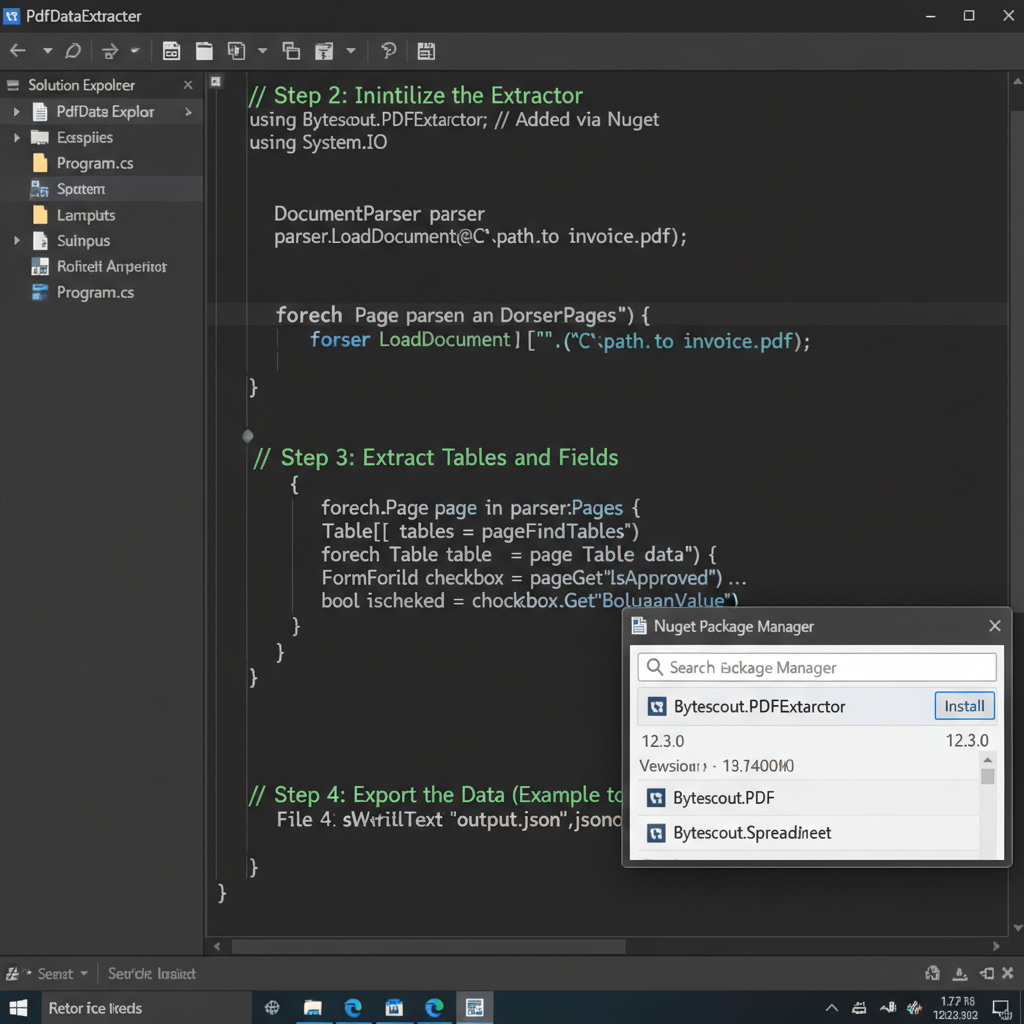
Open your Visual Studio project, navigate to the NuGet Package Manager, and install your chosen PDF extraction library (e.g., Bytescout.PDFExtractor).
Instantiate the library's document parser class in your C# code and load your target PDF file into the object.
Use the library's specific methods to iterate through the document pages. Call functions like ExtractTable() to get grid data and GetFormField() to check the boolean states of checkboxes.
Map the retrieved variables into your application's data models and export them to your required format, such as a database, JSON, or CSV file.
Utilize a No-Code Document Parsing API
Use cloud-based parsing services like Docparser to extract data via an HTTP API, avoiding the need to write complex extraction logic in C#.
Extract PDF Tables to Excel Instantly with WPS Office
If you need to extract tables and form data quickly without writing complex C# scripts, WPS Office provides a powerful built-in PDF to Excel converter that accurately recognizes tables, text, and formatting.
- 1. Open your PDF: Launch WPS Office and open the PDF document containing the tables and checkboxes you need to extract.
- 2. Access the Converter: Navigate to the 'Tools' tab on the top ribbon and select the 'PDF to Excel' option.
- 3. Select Pages and Convert: Choose the specific pages containing your data and click 'Convert' to generate the spreadsheet.
- 4. View Extracted Data: Open the newly created Excel file to view, edit, and analyze your accurately extracted tables.

Frequently Asked Questions
Can C# libraries extract tables from scanned PDF files?
Yes, but you will need an extraction library that supports Optical Character Recognition (OCR). Standard libraries only read embedded text layers, while OCR-capable libraries can process images to identify text and table borders.
How do PDF libraries detect checkbox values?
If the PDF contains interactive form fields, libraries read the underlying field dictionary to check its state. If the PDF is flattened or scanned, libraries use Optical Mark Recognition (OMR) to visually detect if a specific rectangular area contains a checkmark or cross.
Are there free C# libraries for PDF table extraction?
Yes, open-source libraries like iText7 and PDFBox are available. However, parsing unstructured tables or detecting complex borders often requires writing custom logic, whereas commercial solutions generally offer higher out-of-the-box accuracy.


