

How to Fix Ctrl+F Finding No Matches in Acrobat PDF

Question details
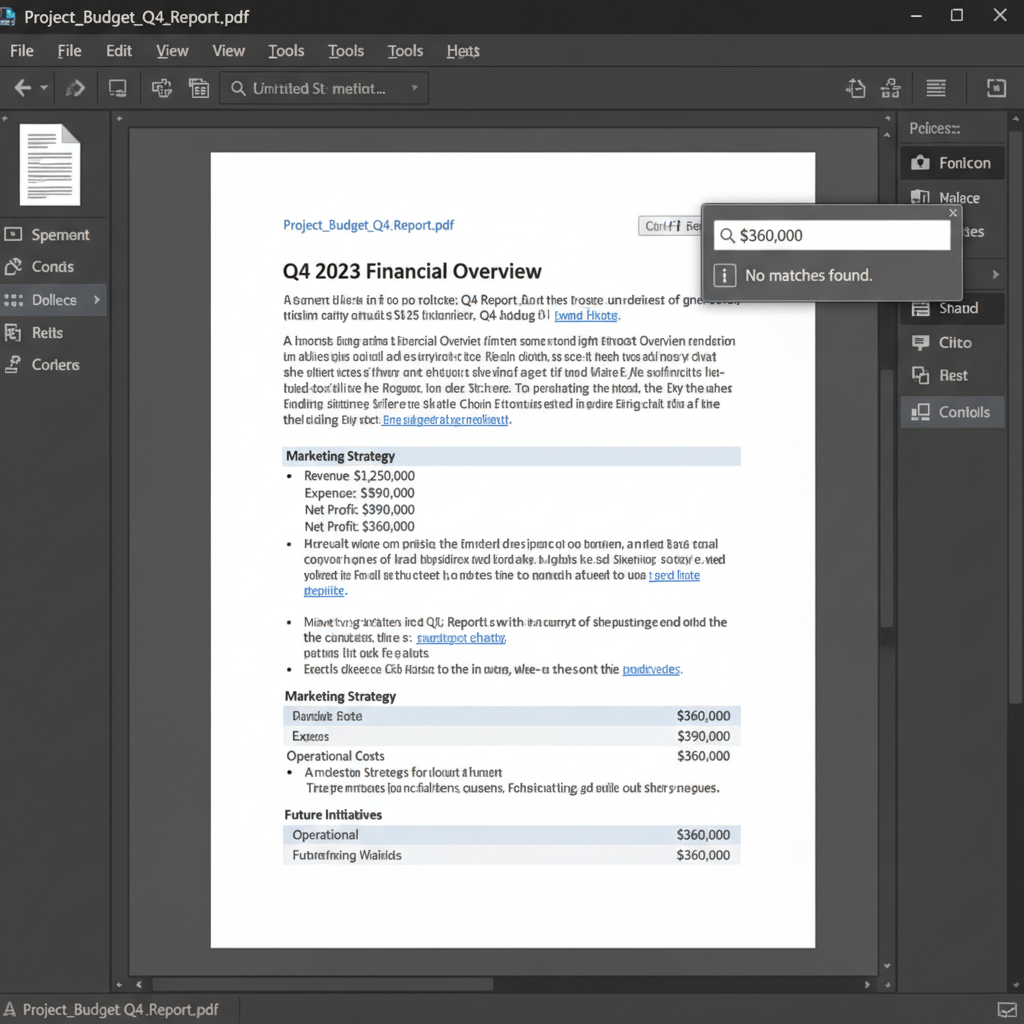
The user is unable to find visible text or numbers in an Acrobat PDF document using the Ctrl+F search function.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Attempting to search for specific words or numeric values within a PDF document using the standard Find tool (Ctrl+F).
- Observed behavior
- The Find tool reports that no matches are found, despite the target text or numbers being visibly present on the PDF pages.
Before troubleshooting the search function, try highlighting the text in your PDF with your cursor. If you cannot select individual words, your document is likely an image or a scanned file, which requires text recognition (OCR) before it can be searched.
Run OCR on Scanned or Image-Based PDFs
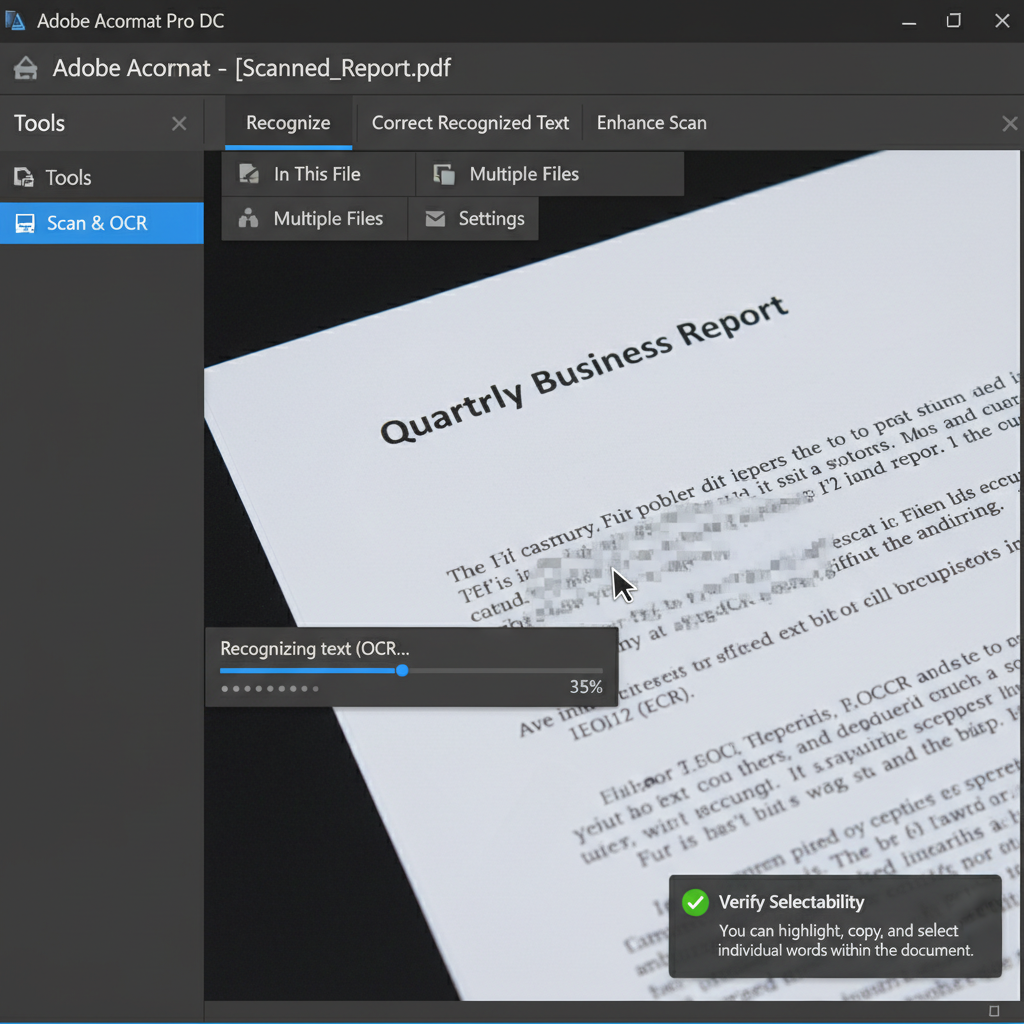
Use Acrobat's Scan & OCR tool to convert image-based text into searchable and selectable text.
The most common reason Ctrl+F fails to find visible words is that the PDF is essentially a photograph of a document. Without a digital text layer, the search function cannot read the contents. Applying Optical Character Recognition (OCR) resolves this by generating readable text over the image.
Open the problematic PDF in Acrobat Pro DC. Go to the 'Tools' menu at the top left and select 'Scan & OCR'.
In the secondary toolbar that appears, click on 'Recognize Text' and choose 'In This File' from the dropdown menu.
Click the 'Recognize Text' button to start processing. Wait for Acrobat to scan the pages and convert the images into readable text.
Once the OCR process is complete, press Ctrl+F and type your keyword to verify that the text can now be found.
Check for Document Corruption or Application Issues
If the text is already selectable but Ctrl+F still fails, isolate the issue by testing other files and checking for software updates.
Make PDFs Searchable Instantly with WPS Office
If you frequently encounter unsearchable scanned PDFs, WPS Office provides a powerful built-in OCR (Optical Character Recognition) tool that quickly extracts text from images, making your documents fully searchable, selectable, and editable.
- 1. Open the PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Extract or Convert Text: Select the option to extract text or convert the file to an editable document. Let WPS Office process the pages.
- 4. Search Your Document: Once the document is processed, simply press Ctrl+F to easily search and find any specific word or number.

Frequently Asked Questions
Why can I visually read the text in my PDF but cannot search for it?
You are likely viewing a scanned document or an image saved as a PDF. Because there is no underlying digital text layer, the search tool cannot detect the words until you apply OCR (Optical Character Recognition) to convert the image into machine-readable text.
What is OCR and why do I need it for PDF search?
OCR stands for Optical Character Recognition. It analyzes the visual shapes of letters in an image or scanned document and converts them into selectable text, which enables search functions like Ctrl+F to locate specific words or phrases.
How can I tell if my PDF is image-based or contains real text?
Try selecting a single word or a sentence with your mouse cursor. If you can highlight individual characters, it contains real text. If the entire page highlights as a single large box or you cannot select anything at all, it is an image-based PDF.
Can corrupted fonts cause the Ctrl+F search to fail?
Yes. If a PDF was created using non-standard or improperly embedded fonts, the visual representation might look correct to the human eye, but the underlying text encoding may be scrambled, preventing the search tool from recognizing the characters.


