

How to Fix Horizontal Lines and Incorrect Characters When Converting PDF to Word

Question details
Users experience formatting issues such as horizontal lines, wrong characters, and misplaced numbers when converting scanned PDF files to Microsoft Word.
- Product
- PDF Converter
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF document to an editable Microsoft Word file using OCR technology.
- Observed behavior
- The resulting Word document contains unwanted horizontal lines, incorrect text characters, and improperly placed numbers due to poor scan quality or complex layouts.
Ensure you have access to a PDF editor or image conversion tool that allows you to export files at a high resolution (at least 300 DPI) to maximize OCR accuracy.
Export as High-Resolution TIFF and Re-run OCR
Improve OCR accuracy by exporting your scanned PDF pages as high-quality TIFF images before converting them back to a PDF and extracting text.
The quality of the resulting Word file heavily depends on the original PDF's scan clarity. Converting poorly scanned PDFs directly often causes OCR engines to misinterpret artifacts as lines or incorrect characters.
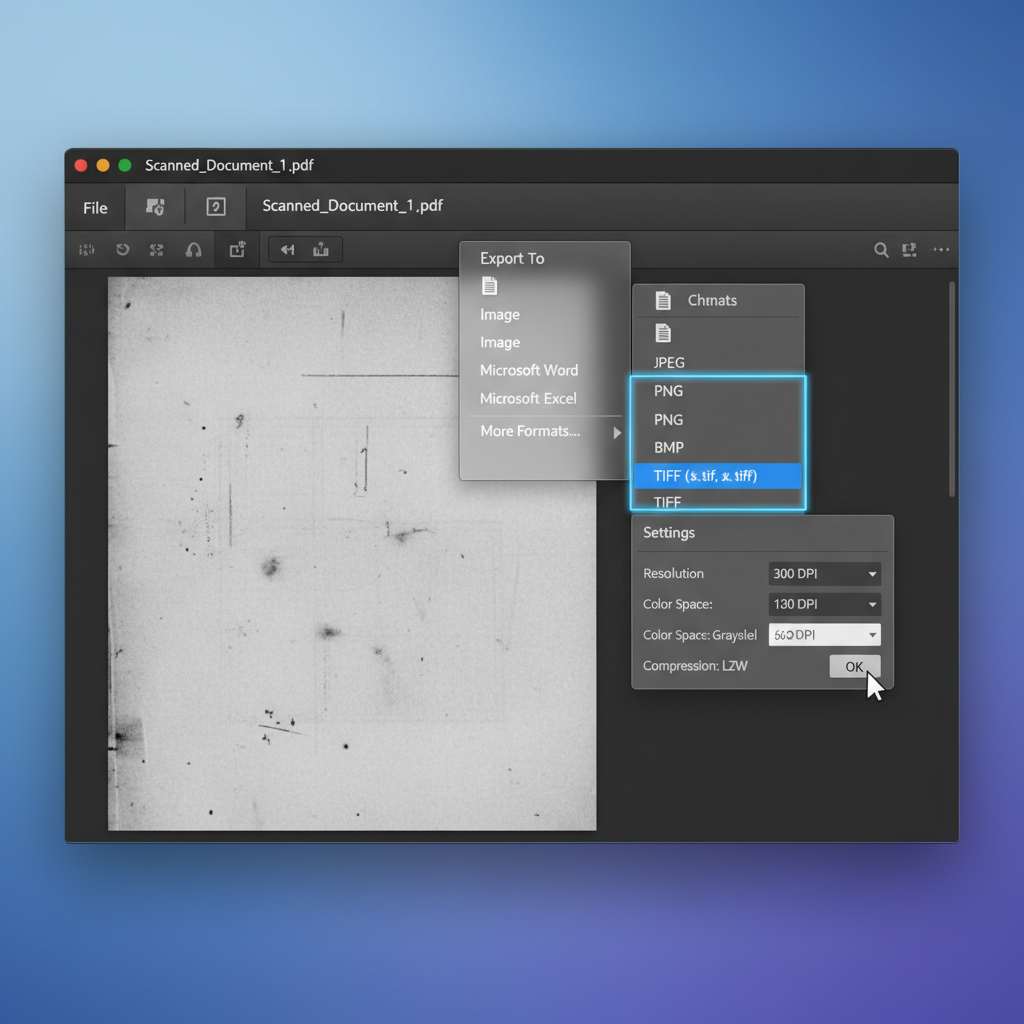
Open your original PDF in your PDF editor and use the Export feature to save the pages as TIFF images. Set the image resolution to approximately 300 DPI.
Combine the newly exported high-resolution TIFF images back into a single, new PDF document.
Use your PDF tool's OCR (Optical Character Recognition) function to recognize the text on the newly created high-quality images.
Save or export the newly processed PDF as a Microsoft Word document. Carefully review the output, as scanned documents may still require minor manual adjustments.
Use WPS Office to Convert Scanned PDFs to Word Accurately
WPS Office features an advanced built-in OCR engine that accurately extracts text from scanned PDFs, minimizing horizontal lines and incorrect characters. It supports high-quality conversions directly into editable Word formats.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Select PDF to Word: Navigate to the 'Tools' tab and click on 'PDF to Word'.
- 3. Enable OCR: Check the OCR option in the conversion prompt to ensure text is extracted accurately from the scanned images.
- 4. Start Conversion: Click 'Start' to convert the file. WPS Office will process the document and automatically open the editable Word file.

Frequently Asked Questions
Why does my converted Word document have random horizontal lines?
Horizontal lines often appear because the OCR engine misinterprets borders, folds in the original scanned paper, or low-resolution scan artifacts as graphical lines. Enhancing the scan resolution to 300 DPI can resolve this.
Can I get a perfect conversion from a scanned PDF to Word?
While modern OCR technology is highly accurate, converting scanned PDFs rarely matches the perfection of documents originally created in Word. Complex layouts, tables, and handwritten notes may require manual correction.
What is the best resolution for scanning documents for OCR?
For optimal OCR results, it is recommended to scan your physical documents or export your images at 300 DPI (Dots Per Inch). This provides the right balance of image clarity and file size for text recognition engines to read characters correctly.
Why are numbers misplaced in the converted document?
Complex layouts, such as multi-column texts or tables without clear borders, can confuse the OCR layout analysis. This results in numbers or text blocks being placed outside their intended reading sequence.


