

How to Fix Japanese OCR Text Not Copying or Indexing Correctly in PDF

Question details
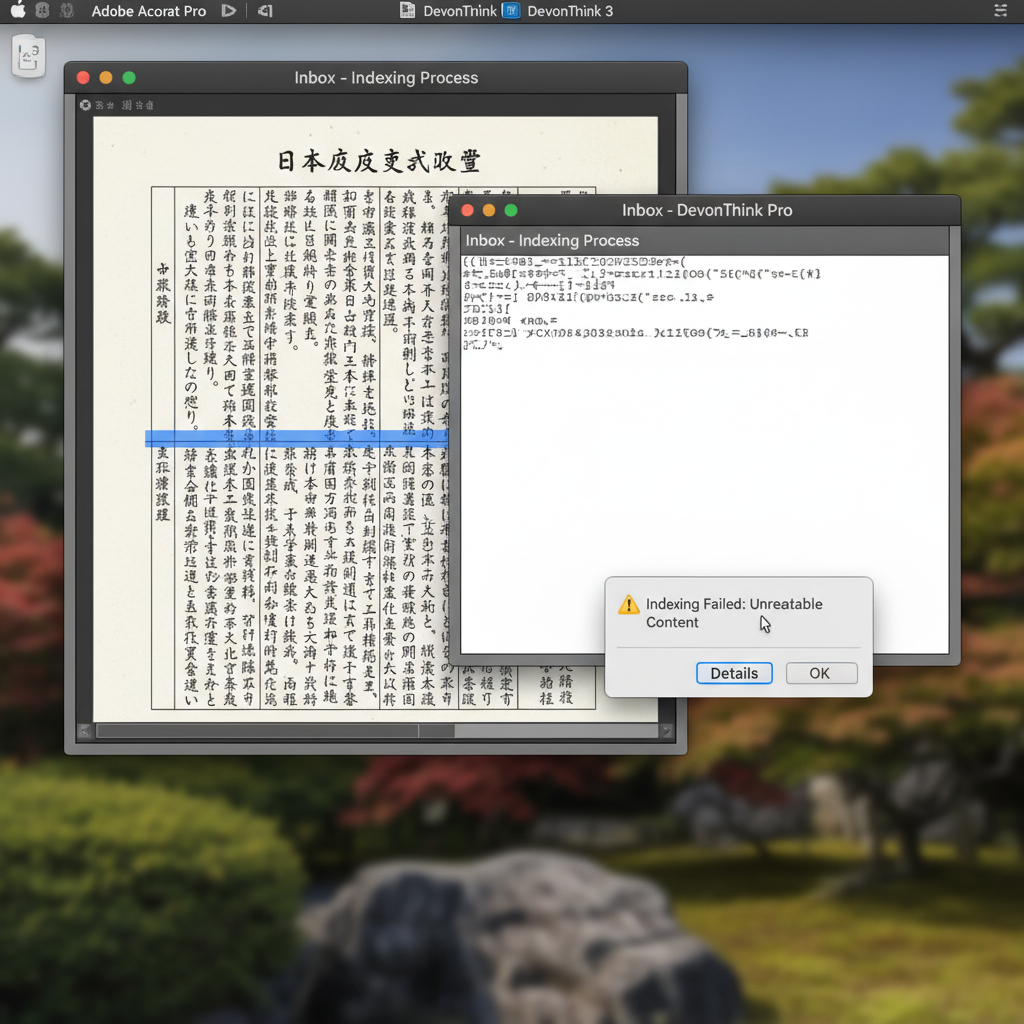
The user is experiencing an issue where Japanese text processed with Adobe Acrobat OCR cannot be correctly copied or indexed by DevonThink, resulting in blank lines or gibberish.
- Product
- Adobe Acrobat
- Device & OS
- macOS
- Scenario
- Attempting to copy text or index scanned Japanese PDF documents in third-party databases like DevonThink.
- Observed behavior
- The recognized text appears visible on the PDF, but copies to the clipboard as blank lines or gibberish and fails to be indexed properly by DevonThink.
Verify that your original scanned document has a high enough resolution (at least 300 DPI) for accurate Japanese character recognition, and create a backup copy of the PDF before re-running the OCR process.
Update macOS and Adobe Acrobat to the Latest Versions
System-level text rendering bugs or application encoding glitches can interfere with font mapping. Updating to the latest macOS and Acrobat versions often resolves these Japanese OCR bugs.
MacOS upgrades frequently include fixes for system-wide font rendering and indexing services that DevonThink relies on. Similarly, Adobe periodically patches Acrobat's OCR engine to handle complex Asian characters better.
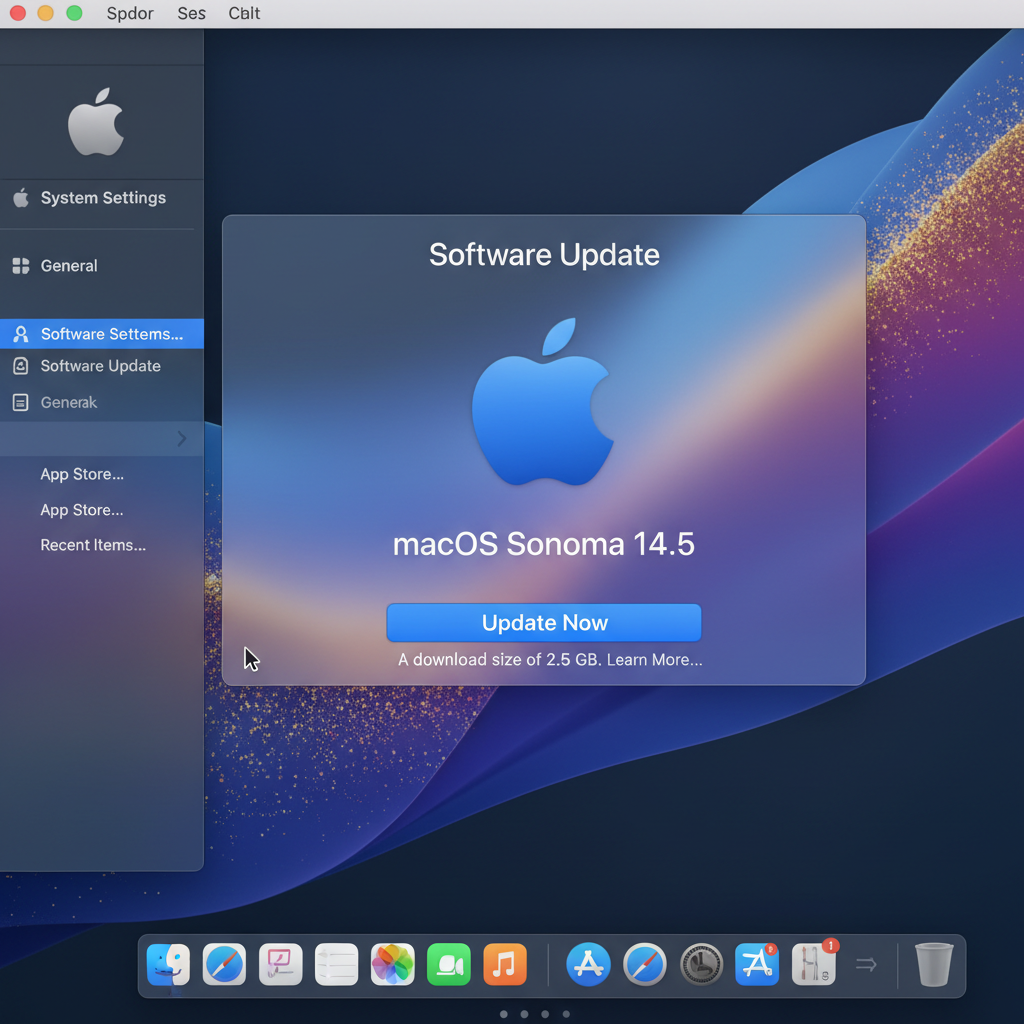
Click the Apple menu > System Settings > General > Software Update. If an update is available, follow the on-screen prompts to install it.
Launch Adobe Acrobat, click on 'Help' in the top menu bar, and select 'Check for Updates'. Install any pending patches.
Restart your computer to ensure all text-indexing services (like Spotlight and DevonThink's indexing core) and font caches are completely refreshed.
Re-run OCR with Specific Japanese Language Settings
Applying the wrong OCR language or using default settings can cause complex Japanese characters to map incorrectly to the embedded font.
Copy Text Without Formatting
Sometimes the underlying text is recognized correctly, but clipboard formatting styles cause other applications to misread the characters.
Use WPS PDF to Extract and Copy Japanese Text Accurately
If your current PDF software struggles to index or copy scanned Japanese documents, WPS PDF offers a highly accurate built-in OCR engine. It seamlessly recognizes complex Asian characters and outputs indexable, copyable text without gibberish issues.
- 1. Open the Scanned PDF in WPS: Launch WPS Office and open your scanned Japanese PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to initiate the text recognition panel.
- 3. Set Language and Extract: Select Japanese as your primary recognition language. Choose whether to extract the text directly to a new document or save it as a searchable PDF.
- 4. Copy the Text Successfully: Once the conversion is complete, select the newly recognized Japanese text, copy it, and paste it into DevonThink or any other application flawlessly.

Frequently Asked Questions
Why does my copied Japanese PDF text appear as blank lines or boxes?
This usually happens when the OCR engine incorrectly maps the recognized characters to the embedded font, or if the clipboard formatting conflicts with the PDF viewer's ability to encode the specific Japanese font used during the OCR process.
Can DevonThink index PDFs if the OCR text is uncopyable?
No. DevonThink relies entirely on the underlying text layer of the PDF. If the text layer is corrupted, outputs as gibberish, or is mapped incorrectly by the OCR software, DevonThink's search indexing will fail to read the contents.
Does the original scan quality affect Japanese OCR accuracy?
Yes, significantly. Japanese characters feature intricate strokes. A scan resolution below 300 DPI, poor contrast, or skewed pages can cause the OCR engine to misinterpret characters, leading to gibberish text output and failed indexing.
How do I fix Acrobat Preflight font errors related to OCR?
You can often resolve Preflight font errors by printing the document to a new PDF (or flattening it) to strip problematic hidden text layers. Afterward, re-run the OCR process from scratch using the 'Searchable Image' setting with the correct language selected.


