

How to Fix PDFs Rendering as Images Instead of Selectable Text

Question details
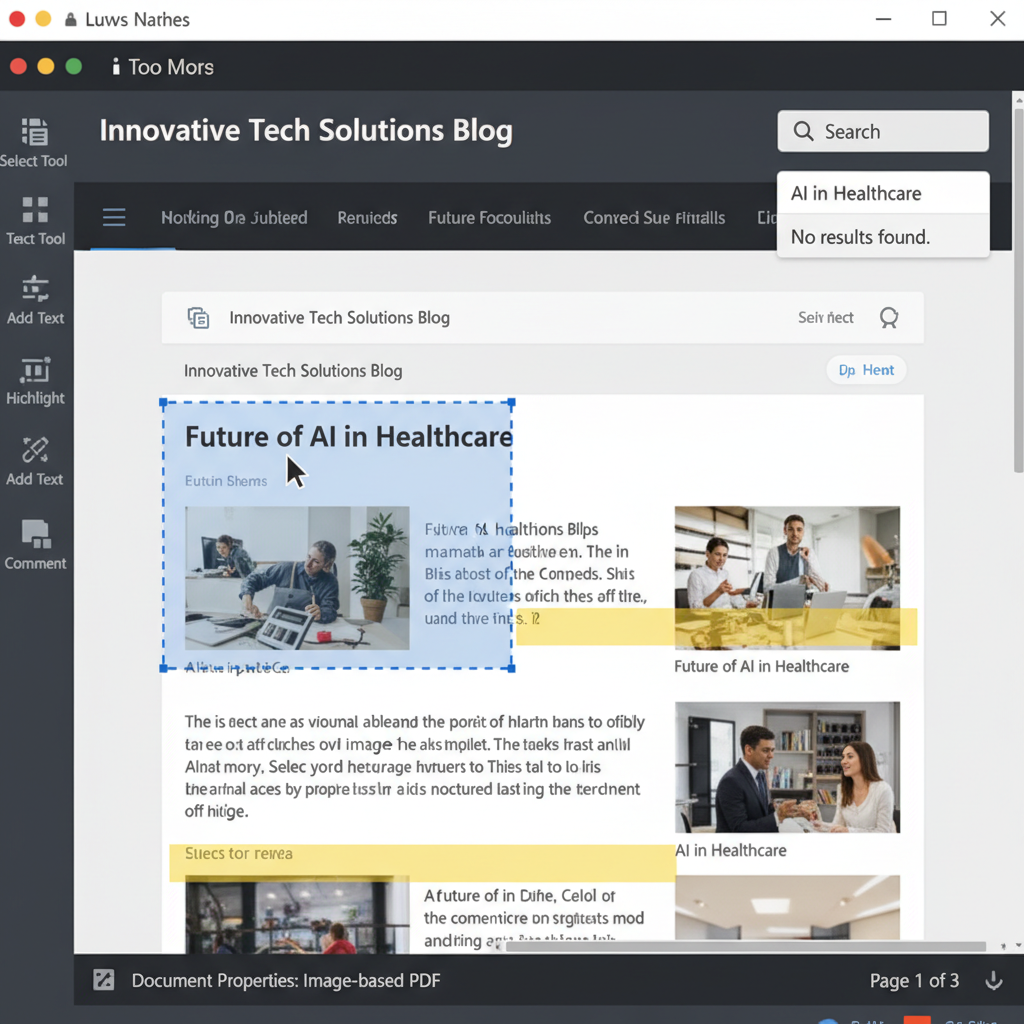
The user is unable to select, highlight, or search text in a PDF created from a web page because the document content renders as an image, even after attempting basic OCR.
- Product
- Device & OS
- not provided
- Scenario
- Converting web pages to PDF formats or interacting with PDFs that seemingly contain text but behave like flat images.
- Observed behavior
- Text within the PDF cannot be highlighted, selected, or searched because the elements are image-based, and standard OCR attempts may fail or yield poor accuracy on mixed content.
Before attempting to extract text, check the original source web page to verify whether the content was actually standard HTML text or a graphic image containing text (like a scanned photo or banner).
Extract Selectable Text Using an OCR Tool
Apply Optical Character Recognition (OCR) to analyze the image-based PDF and convert recognized visual characters into fully selectable, editable text.
If the web page originally contained scanned images, photographs of text, or handwritten notes, the resulting PDF will naturally preserve them as unselectable images. OCR software bridges this gap by digitally reading and recreating the shapes of the letters into computer text.
Launch your preferred PDF editor (such as Adobe Acrobat or WPS PDF) and open the image-based PDF file.
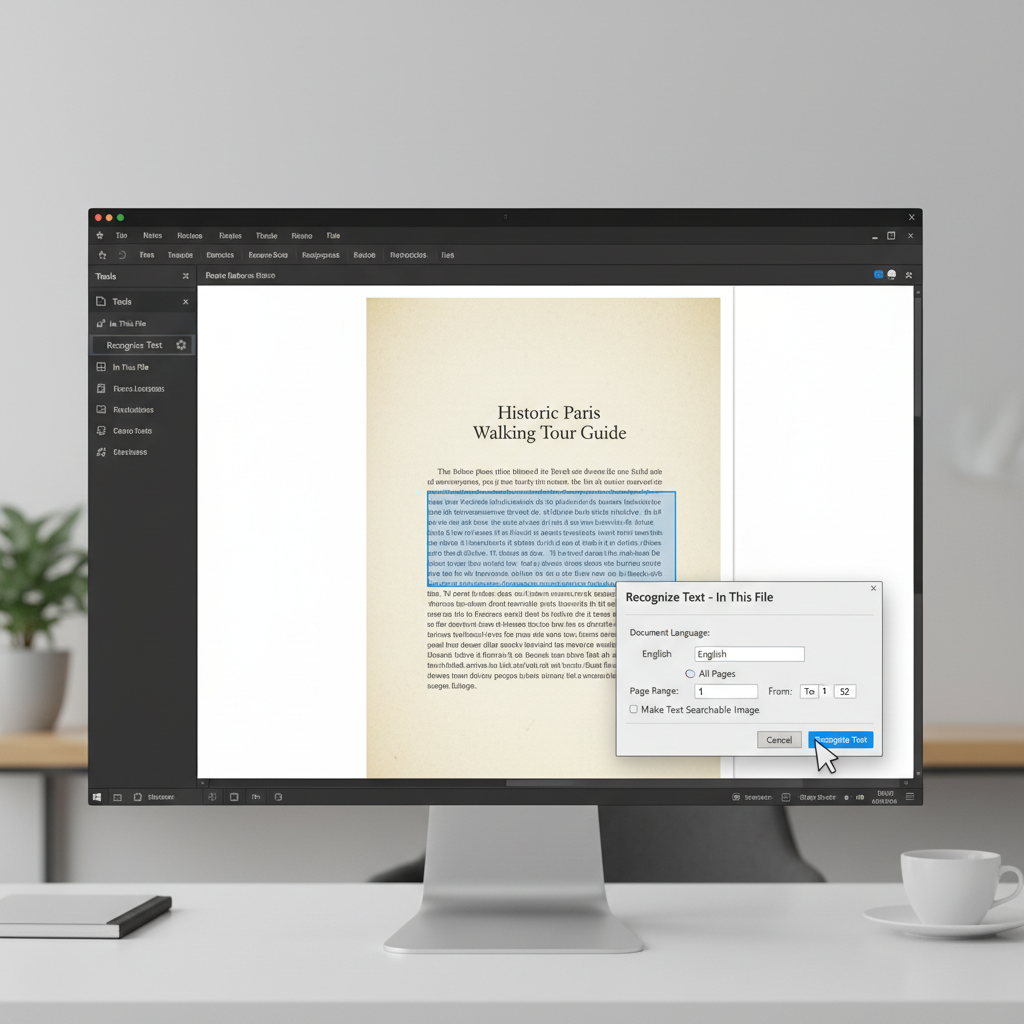
Navigate to the 'Tools' menu and select 'Recognize Text' or 'OCR'. In some software, you may find this under an 'Edit PDF' or 'Convert' tab.
Choose the correct document language and specify which pages you want to scan to improve recognition accuracy.
Click 'Start' or 'Recognize' to begin. Once finished, try highlighting the text with your cursor to confirm it is now selectable.
Use Native Web-to-PDF Converters
Use dedicated web-to-PDF browser extensions instead of the standard 'Print to PDF' function, which sometimes flattens web content into unselectable images.
Easily Convert Scanned PDFs to Selectable Text with WPS Office
WPS Office includes an advanced PDF editor equipped with robust OCR technology. You can effortlessly extract text from image-based PDFs, making your web-converted documents instantly searchable, selectable, and fully editable without needing expensive software.
- 1. Open your PDF in WPS Office: Launch WPS Office, go to the PDF section, and open your unselectable, image-based PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' or 'Home' ribbon at the top of the interface and click the 'OCR' button.
- 3. Select your extraction method: Choose 'Extract Text' if you just need to copy the words, or 'Convert to Editable PDF' to modify the text directly within the document.
- 4. Highlight and edit: Wait a few seconds for the scan to complete. You can now freely highlight, copy, search, or edit the previously inaccessible text.

Frequently Asked Questions
Why did my web page save as an image PDF instead of text?
This usually happens if the text on the website was actually embedded within an image file (like an infographic or scanned document), or if your 'Print to PDF' virtual printer flattened the web page's HTML layers into a single rasterized graphic to preserve visual formatting.
Why didn't OCR work perfectly on my document?
OCR relies on recognizing specific shapes of letters. If the original web image was blurry, low-resolution, contained mixed fonts, featured complex handwriting, or had overlapping graphics, the OCR engine may struggle to accurately convert the image into digital text.
How do I know if my PDF is an image or text?
Try clicking and dragging your text cursor over the words. If a blue highlight box snaps neatly to individual letters and words, the document contains selectable text. If the cursor draws a large rectangular selection box over the whole page or graphic, it is an image.


