

How to Improve Hebrew OCR and Text-to-Speech in PDF Documents

Question details
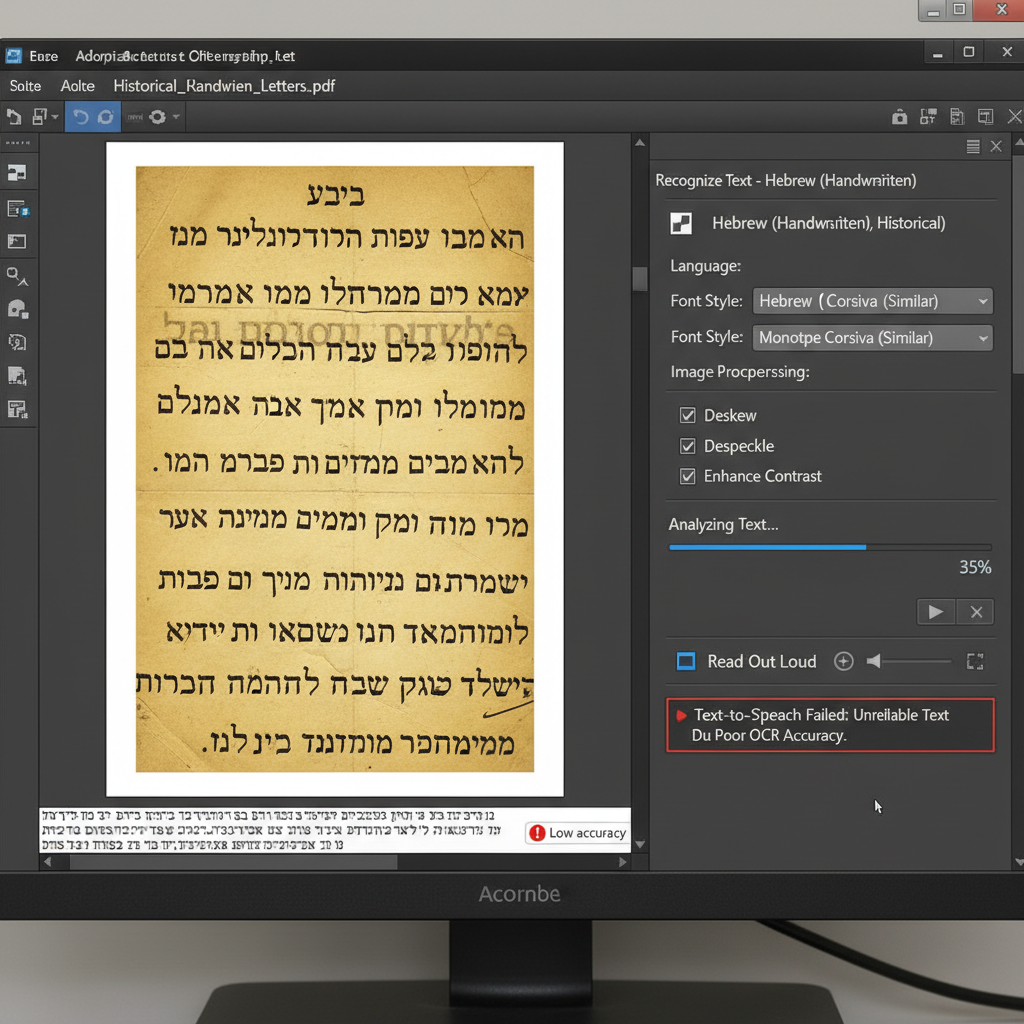
The user needs a method to accurately perform Optical Character Recognition (OCR) and text-to-speech on old, handwritten Hebrew letters and photographs stored in PDF format.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Attempting to extract, recognize, and potentially translate text from photographed historical documents written in a handwritten Hebrew dialect.
- Observed behavior
- Standard PDF OCR fails or performs poorly on handwritten text, historical dialects, and photographs, leading to inaccurate text extraction and unreliable text-to-speech results.
Ensure your document scans or photographs are high-resolution, straightened, and feature high contrast between the text and the background before attempting any OCR process.
Optimize Scan Quality and PDF OCR Settings
Improve printed Hebrew OCR results by maximizing the quality of the source image and explicitly setting the correct recognition language.
Standard OCR engines are highly sensitive to image quality and language configurations. By providing a clean, straightened image and forcing the engine to use a Hebrew dictionary, you can significantly reduce recognition errors.
Re-scan the document at 300 DPI or higher. Use an image editor to crop out borders, straighten the page, and increase the contrast so the text stands out clearly against a white background.
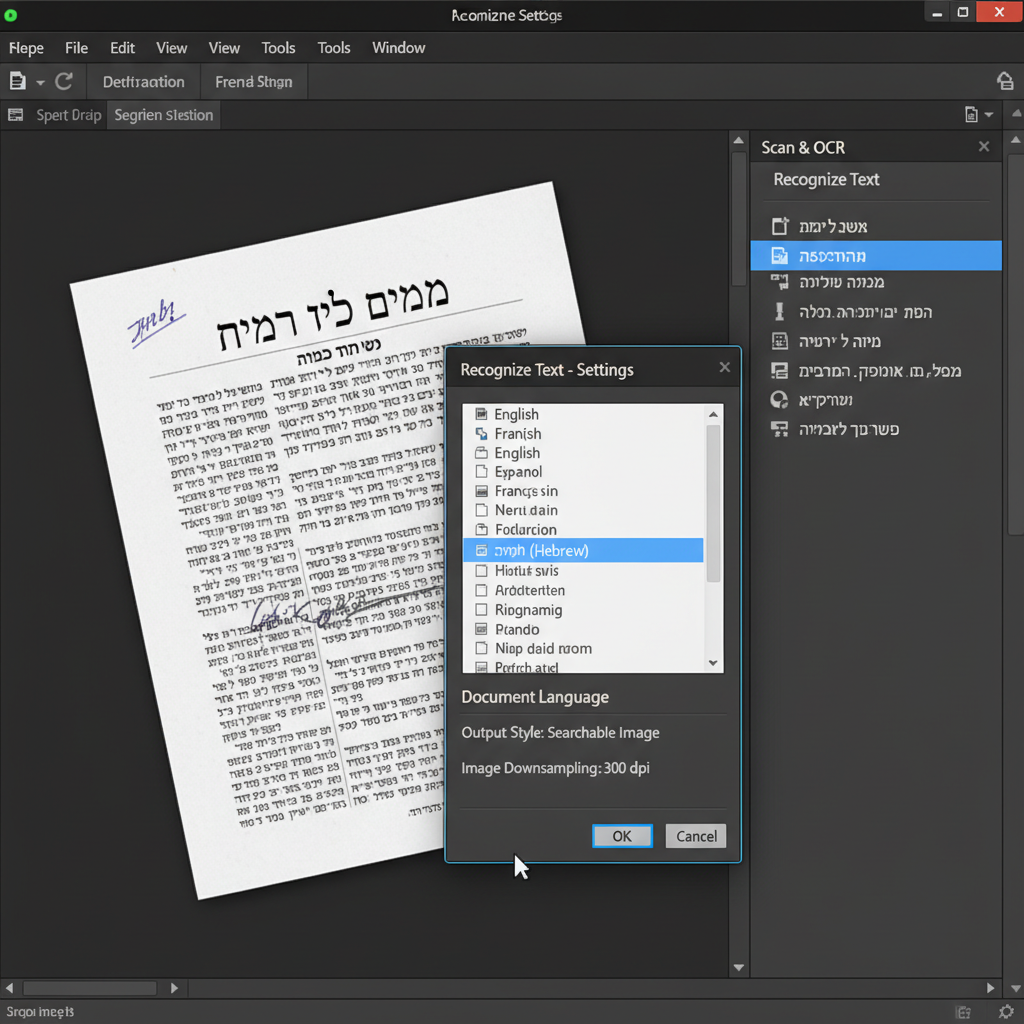
Open your PDF file in your advanced PDF editor (such as Adobe Acrobat Pro). Navigate to the 'Scan & OCR' or 'Recognize Text' tool from the right-hand pane or the Tools menu.
Click on 'Settings' or 'Options' within the OCR menu. Locate the 'Document Language' dropdown and explicitly change it to 'Hebrew' instead of relying on automatic language detection.
Once the OCR process finishes, manually review the generated text layer for errors. Correct misrecognized characters, then test the document with an updated accessibility screen reader to verify the text-to-speech output.
Address Handwritten and Historical Dialects
Standard PDF OCR software is not designed for handwritten or historical text. You must use specialized tools or expert assistance for these scenarios.
Extract Text from Scanned PDFs with WPS Office
WPS Office provides a highly capable, built-in OCR feature designed to easily extract printed text from scanned PDFs and image files, converting them into editable documents.
- 1. Open your scanned document: Launch WPS Office and open your scanned PDF or image file.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button to initiate the text recognition tool.
- 3. Choose your extraction mode: Select whether you want to extract the text to a plain text file or convert the entire scanned layout into an editable Word document.
- 4. Save your editable file: Allow the software to process the document. Once completed, review the extracted text and save it to your preferred format.

Frequently Asked Questions
Why does standard OCR fail on handwritten documents?
Standard Optical Character Recognition (OCR) engines are trained to recognize uniform, standardized printed fonts. Handwritten text features unpredictable character shapes, inconsistent spacing, and connected strokes, making it nearly impossible for conventional software to interpret accurately.
How can I make my PDF screen-reader friendly in Hebrew?
To make a Hebrew PDF accessible, you must ensure the text is fully recognized via OCR with Hebrew set as the primary language. Additionally, you must manually correct any recognition errors in the text layer and ensure your operating system's screen reader has the appropriate Hebrew voice packages installed.
Can I automatically translate an old handwritten letter after scanning it to PDF?
No, automatic translation requires a perfect, machine-readable text source. Because standard OCR cannot accurately digitize old handwritten dialects, any automatic translation attempt will fail. The document must first be transcribed into digital text manually or via specialized Handwriting Text Recognition (HTR) AI before it can be translated.


