

How to Preserve Tables and Layouts When Using Acrobat OCR

Question details
The user wants to know how to maintain original document structures like tables, tally marks, and symbols when running OCR on scanned files.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
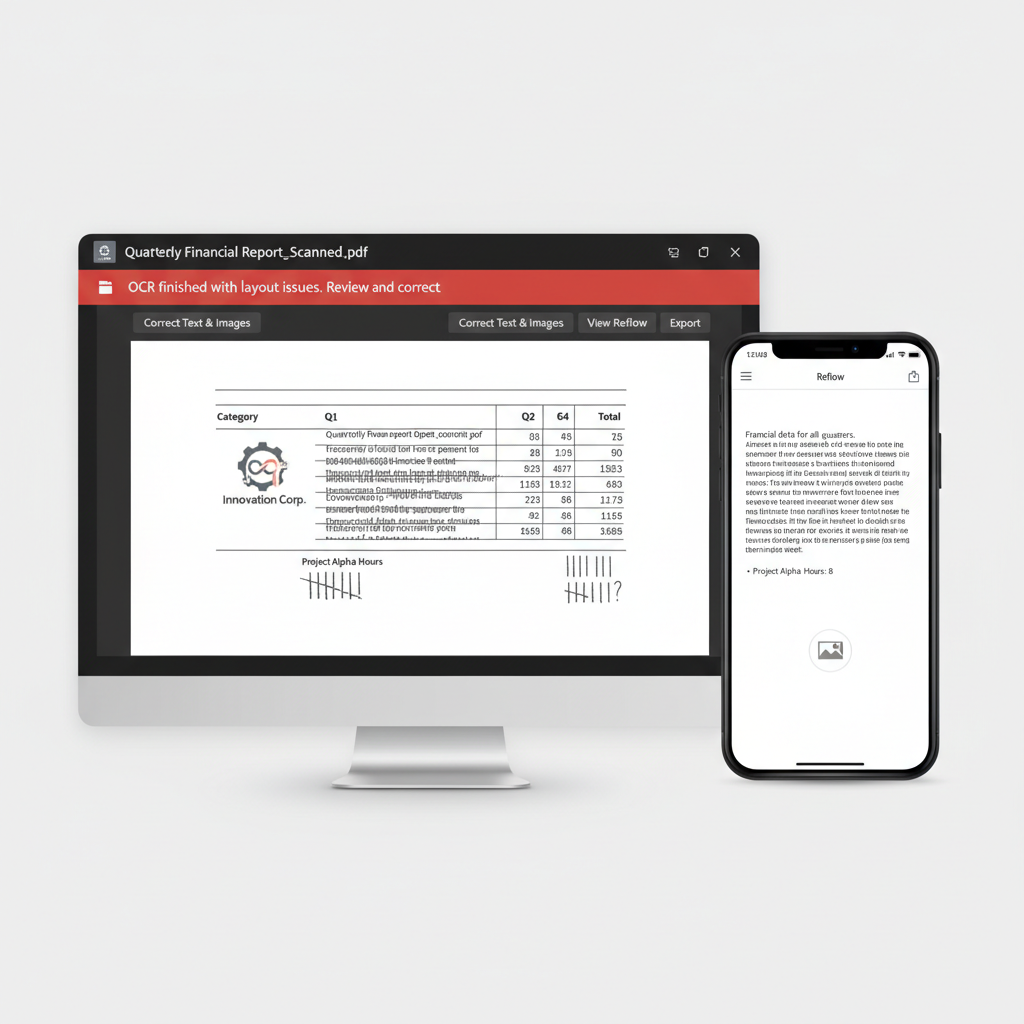
- Running OCR on scanned PDFs to make them searchable and reformat them for smartphone viewing.
- Observed behavior
- Acrobat OCR recognizes the text but often fails to preserve tables, symbols, or text inside images, making the layout difficult to read or reformat.
Ensure your scanned document has a high resolution (at least 300 DPI) and good contrast, as better image quality significantly improves an OCR engine's ability to detect table borders and symbols.
Use Dedicated OCR Software for Complex Layouts
Because Acrobat OCR is primarily designed to place recognized text invisibly behind the original scanned image rather than reconstruct tables, specialized OCR tools are required for heavy table extraction.
Acrobat OCR excels at creating searchable PDFs. However, it is not a full-featured structural OCR replacement. If your workflow heavily relies on accurately extracting tables, tally marks, and complex layouts, you should use dedicated OCR software designed explicitly to rebuild document structures.
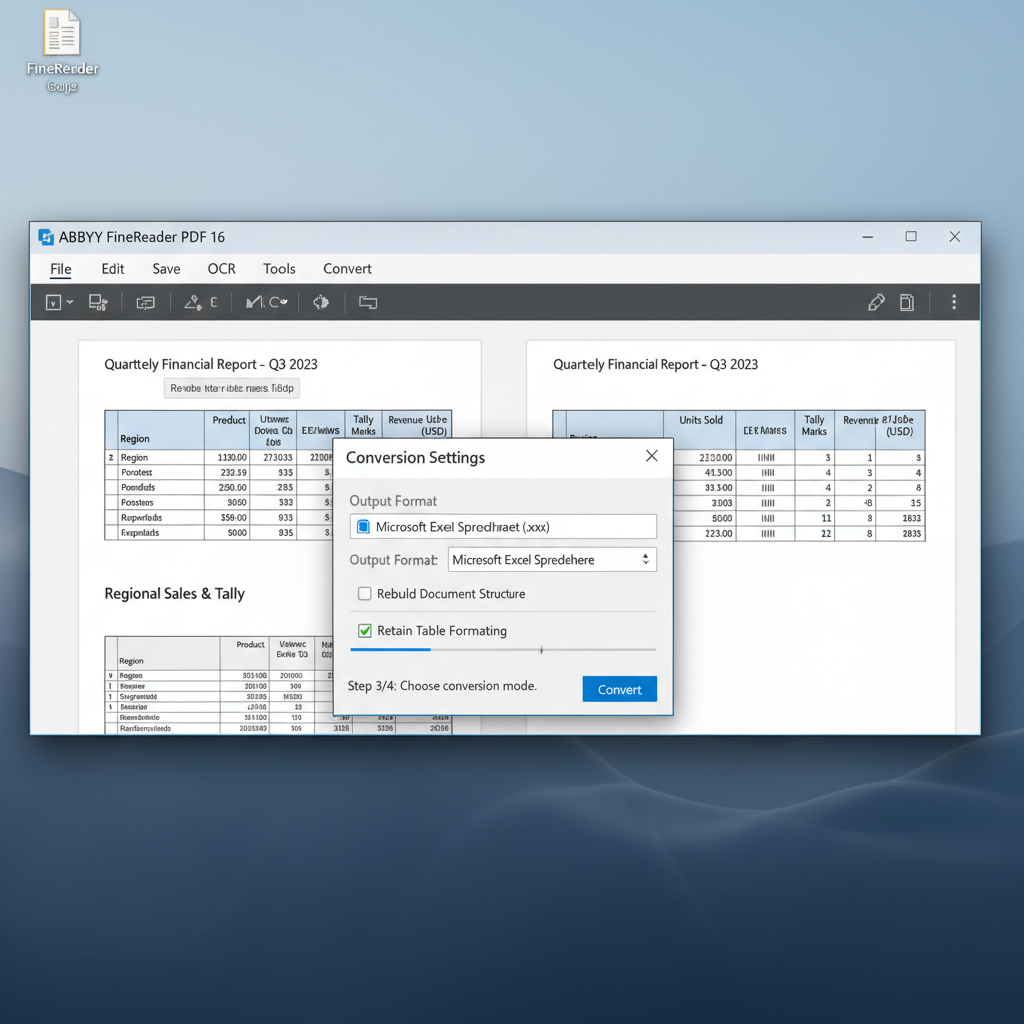
Choose an advanced OCR software specifically designed for data extraction and layout retention (such as WPS Office, ABBYY FineReader, or specialized table extraction tools).
Open the software and upload the scanned document containing the tables and symbols you need to extract.
Select an output format that natively supports tables, such as Microsoft Excel (.xlsx) or Microsoft Word (.docx), to ensure the software actively attempts to rebuild the grid structure.
Initiate the conversion process. Once complete, review the output document to ensure the columns, rows, and symbols have been accurately preserved.
Use Acrobat's 'Export PDF' Feature as a Workaround
Instead of using the basic 'Recognize Text' tool, forcing Acrobat to export the PDF into an Excel spreadsheet uses its conversion engine to attempt rebuilding the tables.
Use WPS Office OCR to Convert Scanned Tables Accurately
WPS Office features a powerful built-in OCR engine tailored for layout retention. It accurately recognizes complex tables, symbols, and formatting from scanned PDFs and converts them directly into fully editable Excel or Word documents.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF containing the tables.
- 2. Access OCR tools: Navigate to the 'Tools' tab and select 'PDF to Excel' or 'OCR'.
- 3. Select conversion options: Choose 'Convert to Editable Document' and set the output language to match your document.
- 4. Convert and save: Click 'Start' to let WPS Office intelligently extract the tables and text, then save your newly formatted spreadsheet.

Frequently Asked Questions
Why does Acrobat OCR only recognize text but mess up the layout?
Acrobat's standard 'Recognize Text' feature is primarily designed to make scanned images searchable. It places an invisible layer of recognized text behind the image rather than fully reconstructing the original layout, borders, or tables.
How can I view complex scanned PDF tables on a smartphone?
Viewing fixed-layout scanned PDFs on a small screen requires constant zooming. The best solution is to use OCR to convert the PDF into a responsive format like an Excel spreadsheet or Word document, allowing the mobile app to reflow the text and tables for easier viewing.
Can I edit text directly within a scanned table using Acrobat?
If you use Acrobat's 'Edit PDF' tool, the software will attempt to convert the immediate area into editable text. However, complex tables often break formatting during this process. It is generally better to export the entire document to an Excel file for extensive table editing.
Does the quality of the scan affect table recognition in OCR?
Yes. A higher DPI (dots per inch, ideally 300 or higher) and high contrast between the text and background will significantly improve any OCR engine's ability to accurately identify table borders, tally marks, and special symbols.


