

How to Use OCR Before Comparing Scanned PDFs in Adobe Acrobat

Question details
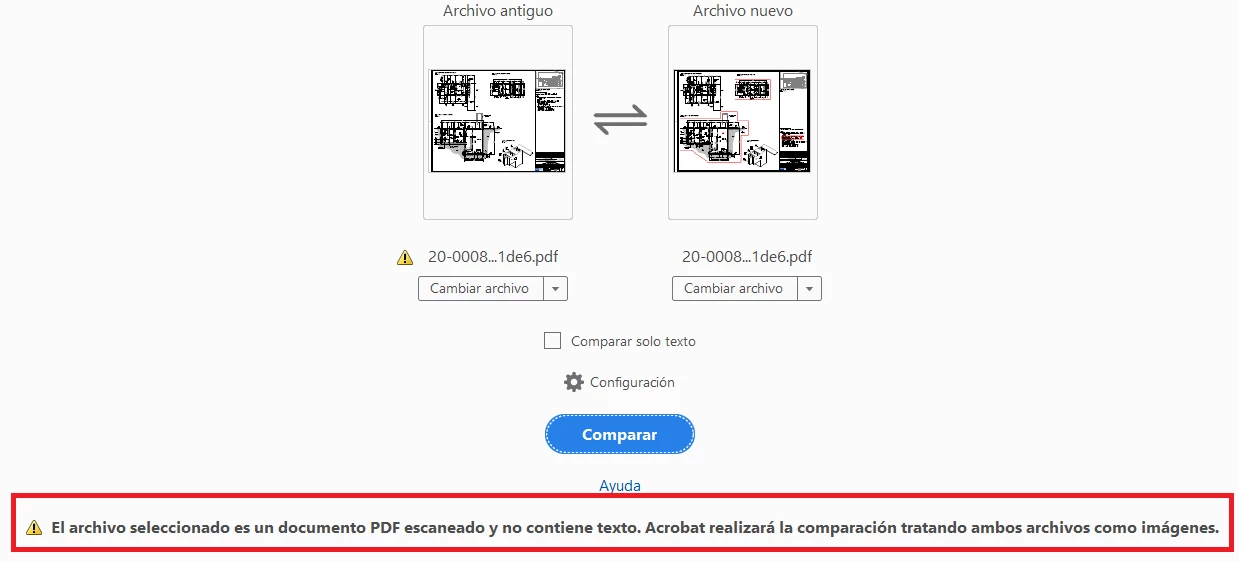
Users need to compare the text of scanned PDF files but face accuracy issues because the software cannot analyze the documents without searchable text layers.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to use the Compare Files feature on two scanned PDF documents to identify textual differences.
- Observed behavior
- The file comparison tool fails to perform a complete or accurate text comparison because the scanned PDFs contain flat images instead of readable, searchable text.
Ensure your scanned PDFs are clear and have a sufficiently high resolution (ideally 300 DPI or higher), as poor image quality and mixed digital content will directly reduce OCR accuracy.
Apply OCR to Convert Scanned Images to Searchable Text
Use the built-in Scan & OCR feature to recognize text within the scanned document before attempting a file comparison.
Because scanned PDFs are essentially photographs of physical pages, PDF readers cannot natively read the text. Applying Optical Character Recognition (OCR) translates these images into real text characters. This step is mandatory before running a text-only comparison.
Launch your PDF application and open the scanned PDF document that needs to be compared.
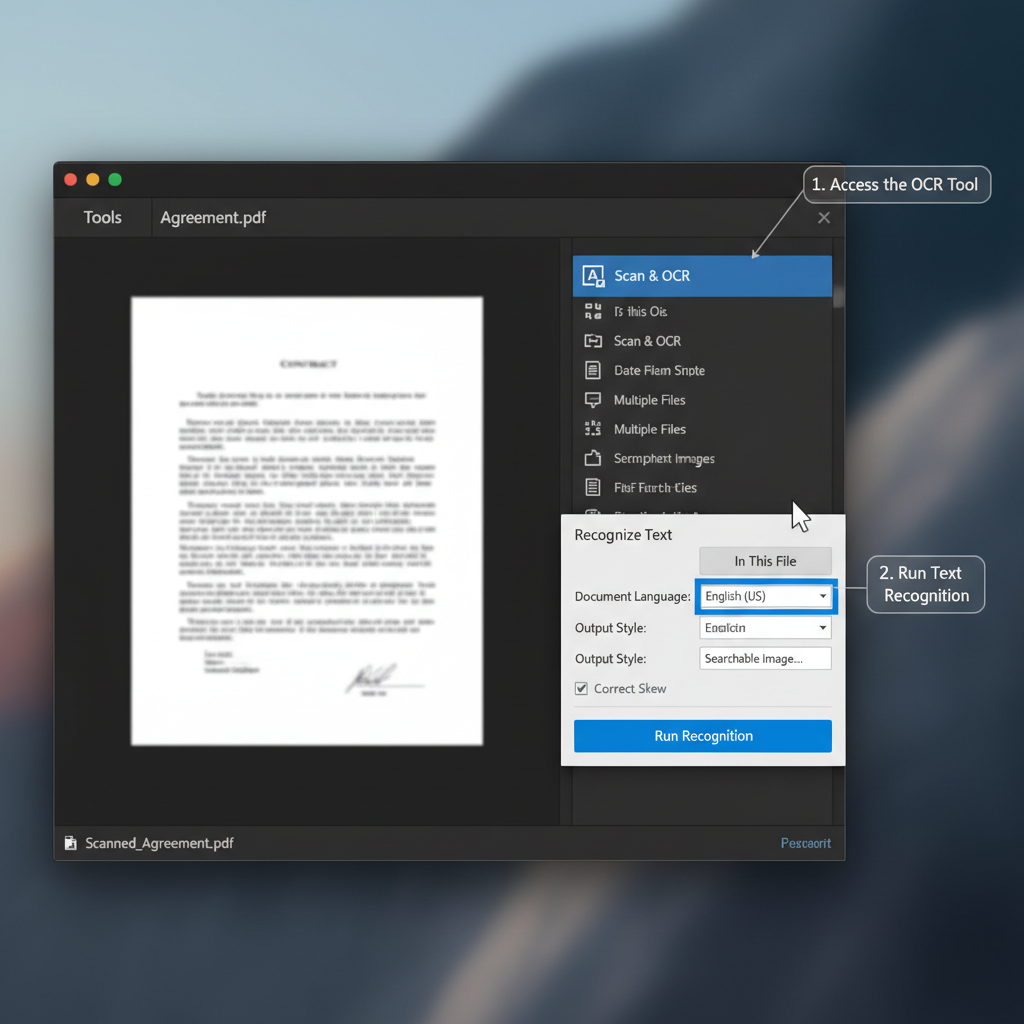
Navigate to the tools menu, locate the 'Scan & OCR' option, and select it to bring up the text recognition features.
Click on 'Recognize Text' and choose 'In This File'. Ensure you select the correct document language and appropriate output settings, then start the process.
Once OCR is complete, quickly review the document for any recognition errors. Finally, open the 'Compare Files' tool, select your OCR-processed documents, and choose the text-only comparison option.
Easily Extract Text and Compare PDFs with WPS Office
WPS Office features a robust PDF toolkit equipped with highly accurate OCR technology. It allows you to quickly convert scanned documents into searchable, editable text and effortlessly compare multiple PDF files.
- 1. Open Your Scanned PDF: Launch WPS Office and open the scanned PDF file you wish to process.
- 2. Extract Text with OCR: Navigate to the 'Tools' tab and select 'OCR'. Follow the prompts to convert your image-based PDF into an editable text document.
- 3. Compare Documents: Open your second document. Go to the 'View' tab and click 'View Side by Side' to easily identify differences between the texts.

Frequently Asked Questions
Why does the compare feature say there is no text to compare?
This happens when your PDF is a scanned image rather than a digitally created document. The software only sees a picture of a page. You must run Optical Character Recognition (OCR) first to convert those images into readable text.
Does the resolution of my scan affect OCR accuracy?
Yes. Image clarity, resolution, and contrast heavily influence how well OCR software can recognize letters. Blurry text or low-resolution scans (under 300 DPI) can result in recognition errors, which will negatively impact your text comparison.
Should I choose 'text-only' comparison after using OCR?
Yes. Scanned documents often have minor visual discrepancies (like slight image shifting or noise) that the software might flag as differences. Choosing a text-only comparison forces the tool to ignore the graphical noise and focus strictly on the recognized words.


