

How to Remove Background from a Scanned PDF After OCR

Question details
The user needs to remove the gray, colored, or textured background left behind on a scanned PDF document after running OCR.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Editing a scanned PDF document post-OCR where the original paper background interferes with document clarity and readability.
- Observed behavior
- OCR successfully recognizes the text, but the original scanned image background remains visible and cannot be cleared using standard background removal commands because it is stored in the image layer.
Before editing, ensure you have a high-contrast, clean original scan of your document, as a good initial scan significantly reduces background noise and improves OCR accuracy.
Use Enhance Scans and Print Production Tools
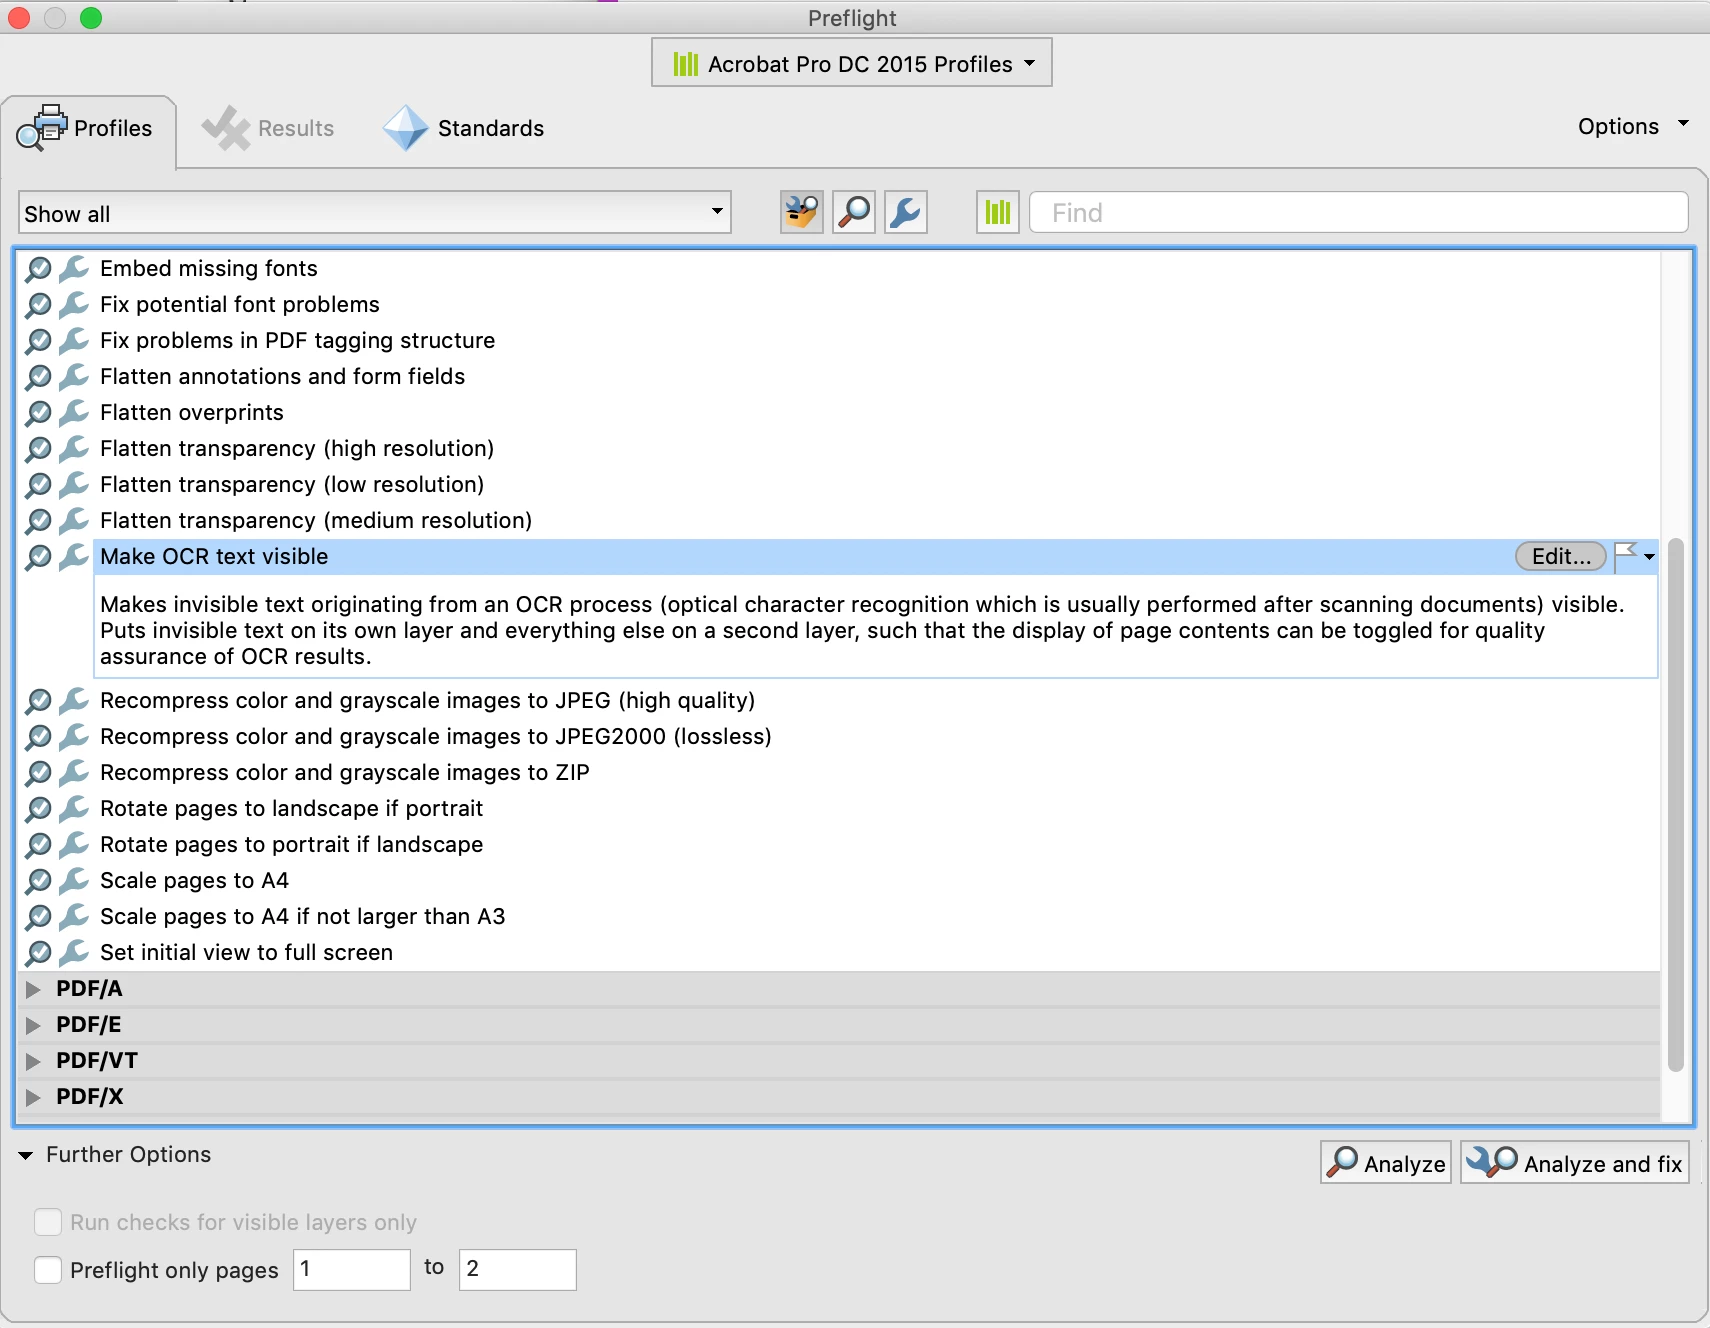
Utilize advanced scan enhancement and preflight fixups to separate and remove the background image layer from the recognized text.
Because a scanned document is essentially a single flat image, standard background removal tools often fail. By using Print Production and Preflight tools, you can isolate the text layer created by OCR from the original scanned image layer.
Open your PDF and navigate to the Enhance Scans tool. Apply high-contrast filters and clean up the page before running your OCR process.
Go to Tools > Print Production and select the Preflight option.
Choose an appropriate fixup profile designed to separate or remove background image content from text layers.
Once the text and image are placed on separate layers, hide or delete the background image layer, then save the document as a new PDF.
Extract Text and Remove Scanned Backgrounds Easily with WPS Office
WPS Office provides a powerful PDF toolkit that includes highly accurate OCR. You can easily extract text from scanned documents, effectively leaving the messy background behind, by converting the scan directly into an editable Word document.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF editor.
- 2. Use the OCR feature: Click on the 'Tools' tab and select the 'OCR' or 'PDF to Word' option to begin text extraction.
- 3. Convert to Word: Choose 'Convert to Word' and complete the process. The conversion extracts the text and leaves the scanned image background behind.
- 4. Edit and save: Open the newly converted, clean document, make any necessary text adjustments, and save it as a clean PDF or Word file.

Frequently Asked Questions
Why does the standard 'Remove Background' command not work on scanned PDFs?
The standard background removal tool usually targets vector backgrounds or solid colors added digitally. In a scanned PDF, the background is part of a single flattened image layer, requiring advanced OCR or layer separation tools to isolate the text from the image.
How can I prevent a gray background when scanning documents?
To prevent gray backgrounds, adjust your scanner's settings before scanning. Increase the contrast and brightness, and use a 'black and white' or 'text' mode instead of grayscale or color.
Can I extract only the text and discard the background image completely?
Yes. The most efficient way to achieve this is to use an OCR tool to convert the scanned PDF into a Word or Text document. This process extracts the recognized characters and automatically discards the original background image.


