

How to Troubleshoot Poor OCR and Batch Processing Stops in Acrobat Pro

Question details
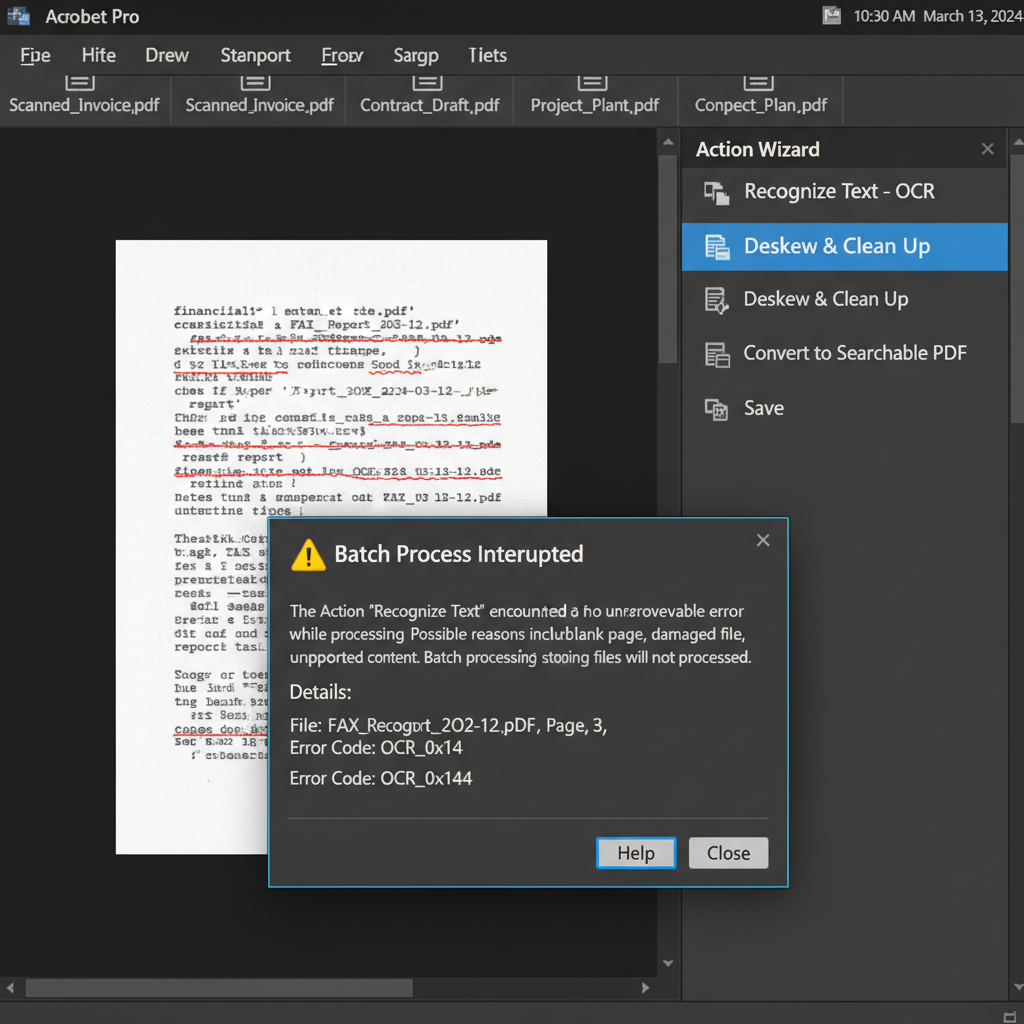
The user needs to resolve text misrecognition during OCR and prevent Action Wizard batch processing workflows from stopping when encountering blank pages or damaged files.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Running Optical Character Recognition (OCR) on scanned or faxed PDFs and using the Action Wizard for batch processing multiple files.
- Observed behavior
- Acrobat Pro misrecognizes characters during OCR, and the Action Wizard batch process halts entirely upon encountering a blank fax or damaged file, preventing remaining files from processing.
Ensure your scanned documents or faxes have a minimum resolution of 300 DPI for optimal OCR results, and separate your files into smaller batches to isolate problematic documents easily.
Optimize OCR Settings and Verify Document Quality
Adjusting scan quality, document settings, and the OCR language can significantly improve character recognition accuracy in Acrobat Pro.
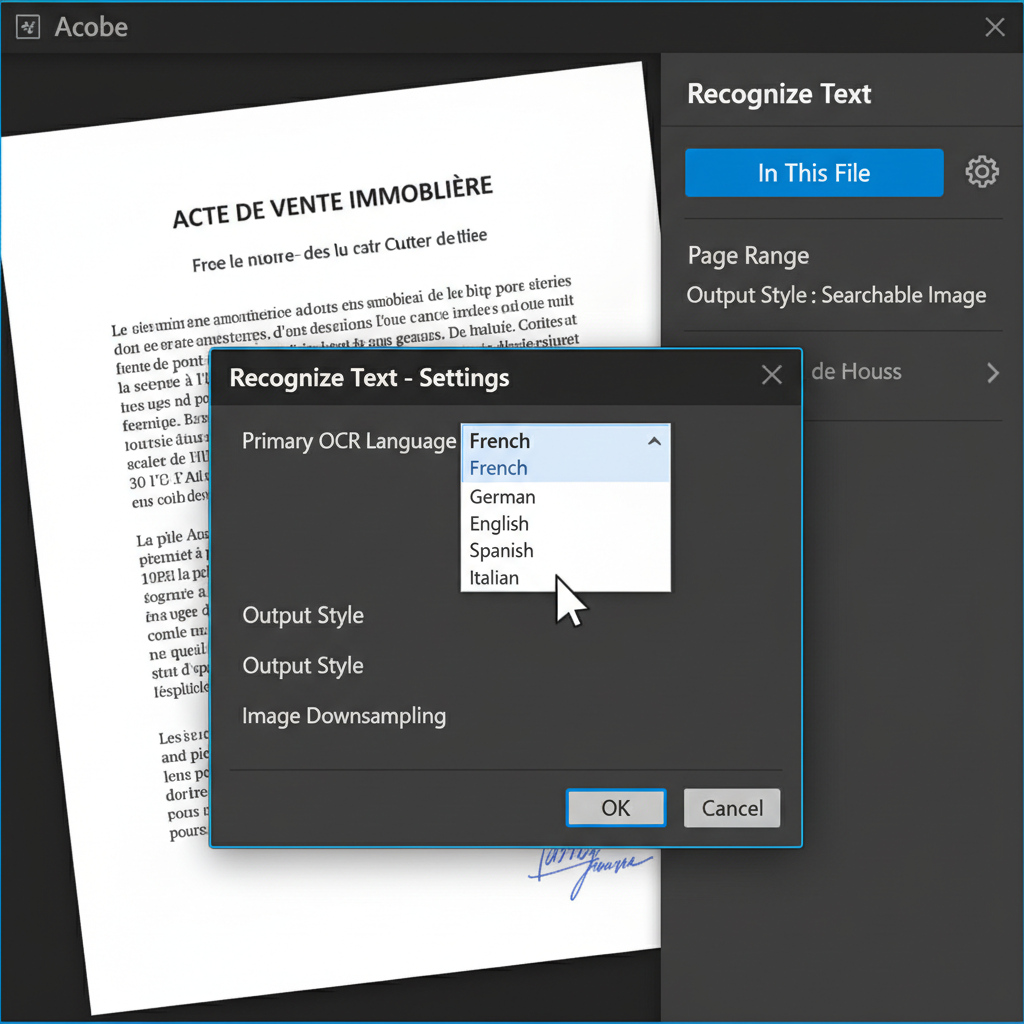
Poor OCR results usually stem from low-resolution scans, incorrect language settings, or interfering renderable text already present in the PDF.
Verify that your original scanned images or faxes were digitized at 300 DPI or higher to provide enough clarity for the OCR engine.
Navigate to the Recognize Text tool in Acrobat Pro, click on Settings, and ensure the 'Primary OCR Language' strictly matches the language of the document.
If you receive a 'renderable text' error, use Acrobat's Preflight tool or export the PDF to high-resolution TIFF images and recombine them to flatten existing text before running OCR again.
Prevent Action Wizard Interruption from Blank Faxes
Modify your workflow to handle or exclude blank pages so the Action Wizard does not halt the entire batch process.
Disable Automatic OCR for Problematic Scans
Turn off the automatic OCR feature to prevent Acrobat from incorrectly altering text on highly degraded scanned documents.
Easily Extract Text from PDFs Using WPS Office
If you are struggling with complex batch processes and OCR errors in Acrobat, WPS Office provides a streamlined, highly accurate OCR tool. It seamlessly extracts text from scanned PDFs and images without the hassle of interrupted workflows.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Extract Text: Select the area or pages you wish to recognize, choose your target language, and click 'Extract Text' to convert the scan into editable content.

Frequently Asked Questions
Why does Acrobat Action Wizard stop processing my batch of PDFs?
The Action Wizard stops when it encounters a fatal error it cannot bypass, such as a completely blank page, a severely corrupted file, or a PDF protected by a password that restricts editing or OCR processes.
What does the 'renderable text' error mean in Acrobat OCR?
This error occurs when Acrobat detects that the PDF already contains a layer of selectable text or vector fonts. Acrobat's OCR engine is designed to run only on flat images, so you must flatten the file or print it to image format before re-running OCR.
Can I automatically delete blank pages from a PDF in Acrobat?
Acrobat does not have a one-click 'delete all blank pages' button, but you can create a custom Preflight fixup profile to detect and remove empty pages, or manually use the Organize Pages tool to delete them before batch processing.
How can I improve OCR results on old, faded fax documents?
To improve recognition on faded faxes, increase the scan resolution to at least 300 DPI, use an image editor to boost contrast and darken the text before converting to PDF, and ensure the correct language is selected in the OCR settings.


