

How to Use PDF Bookmarks as File Names When Extracting Pages

Question details
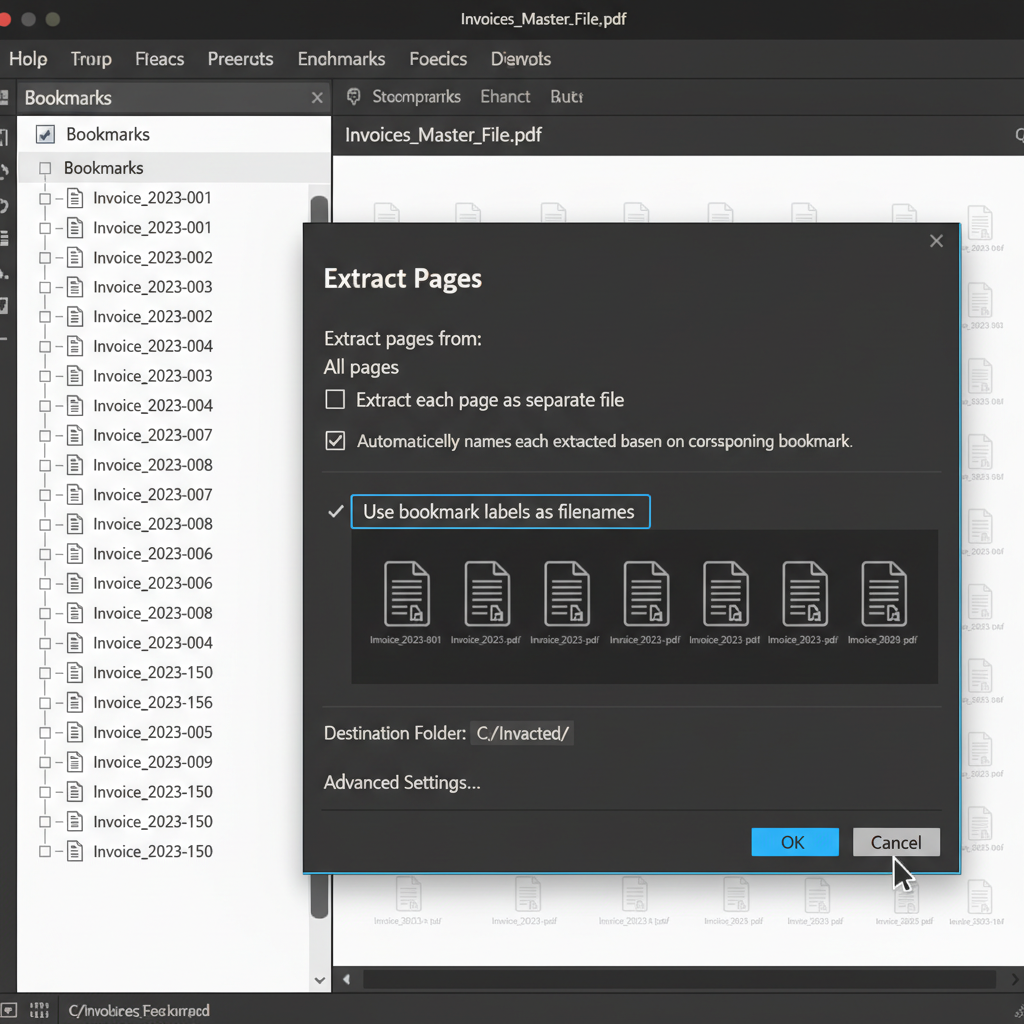
The user needs to extract multiple pages from a single PDF document and automatically save each newly extracted file using its corresponding bookmark label as the file name.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Batch exporting documents, such as individual invoices, stored within a single large PDF file where the PDF bookmarks indicate the specific identities of each document.
- Observed behavior
- Acrobat's standard extraction tool does not automatically use bookmark labels as file names, defaulting instead to appending sequential or page numbers to the original filename.
Ensure that your PDF document has a consistent and correctly structured bookmark list before running any automated extraction scripts or plug-ins.
Use Custom Acrobat JavaScript via Action Wizard
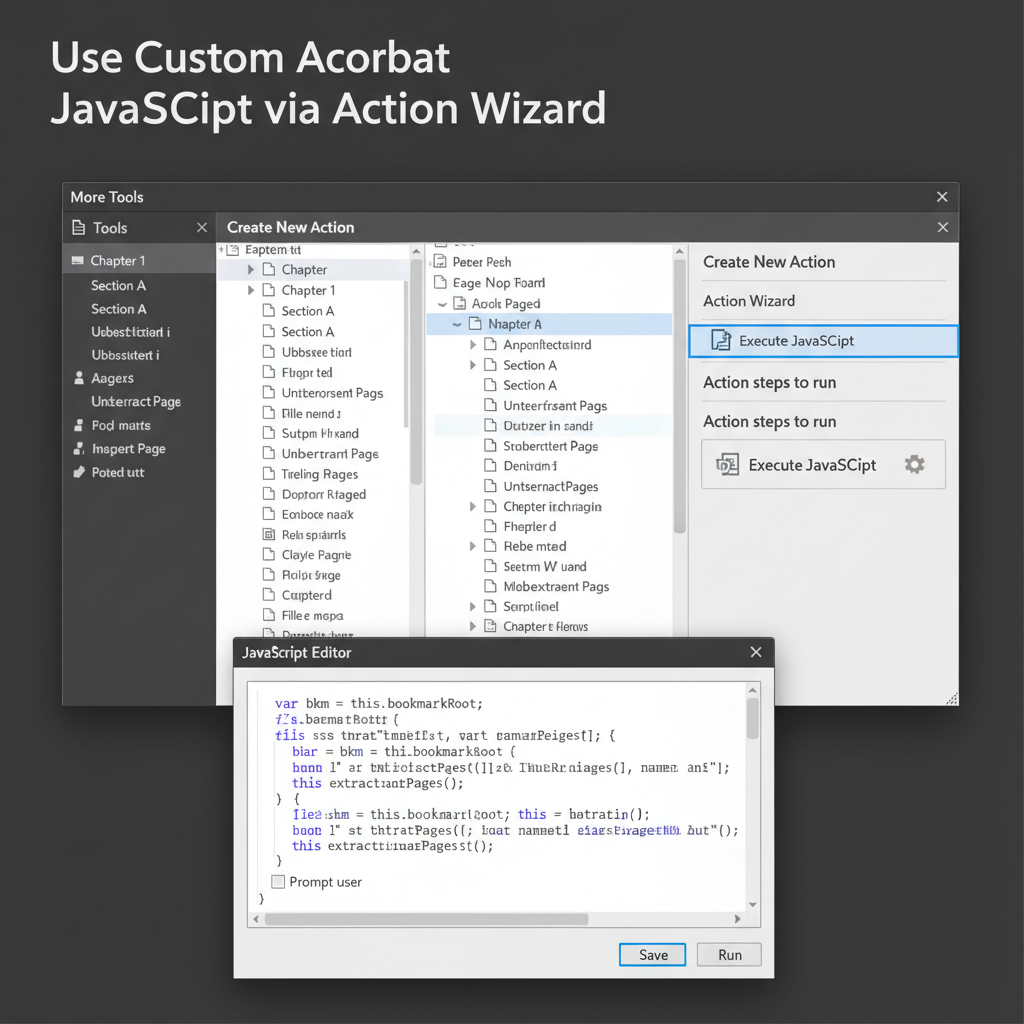
Since Acrobat lacks a native feature for this, you can run a custom JavaScript through the Action Wizard to iterate through the document's bookmarks and extract pages using their labels.
This method requires using Adobe Acrobat Pro. By creating a custom Action, you can execute a script that reads the bookmark tree, identifies the page boundaries, and executes an extraction command specifying the bookmark name as the desired file name.
Navigate to the 'Tools' menu in Adobe Acrobat Pro and open the 'Action Wizard' utility.
Click on 'New Action'. From the left panel under 'More Tools', select 'Execute JavaScript' and add it to your action steps.
Click the gear icon next to the JavaScript step and paste a custom script designed to loop through the 'bookmarkRoot' and trigger the 'extractPages' method for each node. (You may need to acquire a script specific to your file's bookmark depth).
Uncheck 'Prompt user' to allow the script to run seamlessly. Save the Action, then run it on your target PDF.
Use a Third-Party PDF Plug-in
If scripting is too complex or time-consuming, specialized third-party plug-ins for Acrobat offer a user-friendly interface to split PDFs by bookmarks automatically.
Easily Manage and Split PDFs with WPS Office
WPS Office provides robust PDF editing capabilities, including intuitive page extraction tools. It offers a user-friendly interface for managing your documents effectively without the need for complex scripts.
- 1. Open Your PDF: Launch WPS Office and open the PDF document you need to manage.
- 2. Navigate to Page Tools: Click on the 'Page' tab located in the top ribbon menu to view page management options.
- 3. Select Split PDF: Click the 'Split PDF' button to open the document extraction dialog.
- 4. Extract Pages: Configure your preferred page ranges and select an output directory, then click 'Split' to save your new files.

Frequently Asked Questions
Why doesn't Adobe Acrobat use bookmark names by default when extracting pages?
Acrobat's default extraction feature is programmed to append sequential numbers or original page numbers to the primary filename. This prevents file naming conflicts but lacks the ability to dynamically pull text from bookmark metadata without a script.
Can I automatically rename extracted PDF files without using JavaScript?
Within standard Adobe Acrobat, you cannot bypass manual renaming without a script. You would need to use a dedicated third-party PDF splitting tool or a specialized Acrobat plug-in to handle automatic bookmark naming.
Does splitting a PDF by bookmarks retain the original document's formatting?
Yes, extracting or splitting pages from a PDF preserves the original text, layouts, images, and formatting perfectly. The only element that changes is how the pages are grouped into discrete files.


