

Split Large PDF by Employee ID and Auto-Rename Files

Question details
The user needs to split an extremely large PDF (approximately 70,000 pages) by finding specific employee ID numbers, grouping the matching pages together, and automatically naming the exported files based on those IDs.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Processing massive batch documents such as HR records, payrolls, or invoices where individual records need to be extracted and filed automatically based on text identifiers.
- Observed behavior
- Standard Acrobat JavaScript functions struggle to handle the 70,000-page volume, often exceeding memory or processing limits before the batch extraction completes.
Before running any batch extraction scripts or standalone splitting tools, ensure you have sufficient hard drive space for the thousands of exported files and close background applications to free up system memory.
Use a Specialized PDF Splitting Plug-in
For exceptionally large documents exceeding standard scripting limits, dedicated third-party plug-ins or standalone tools offer the processing power and text-pattern recognition required.
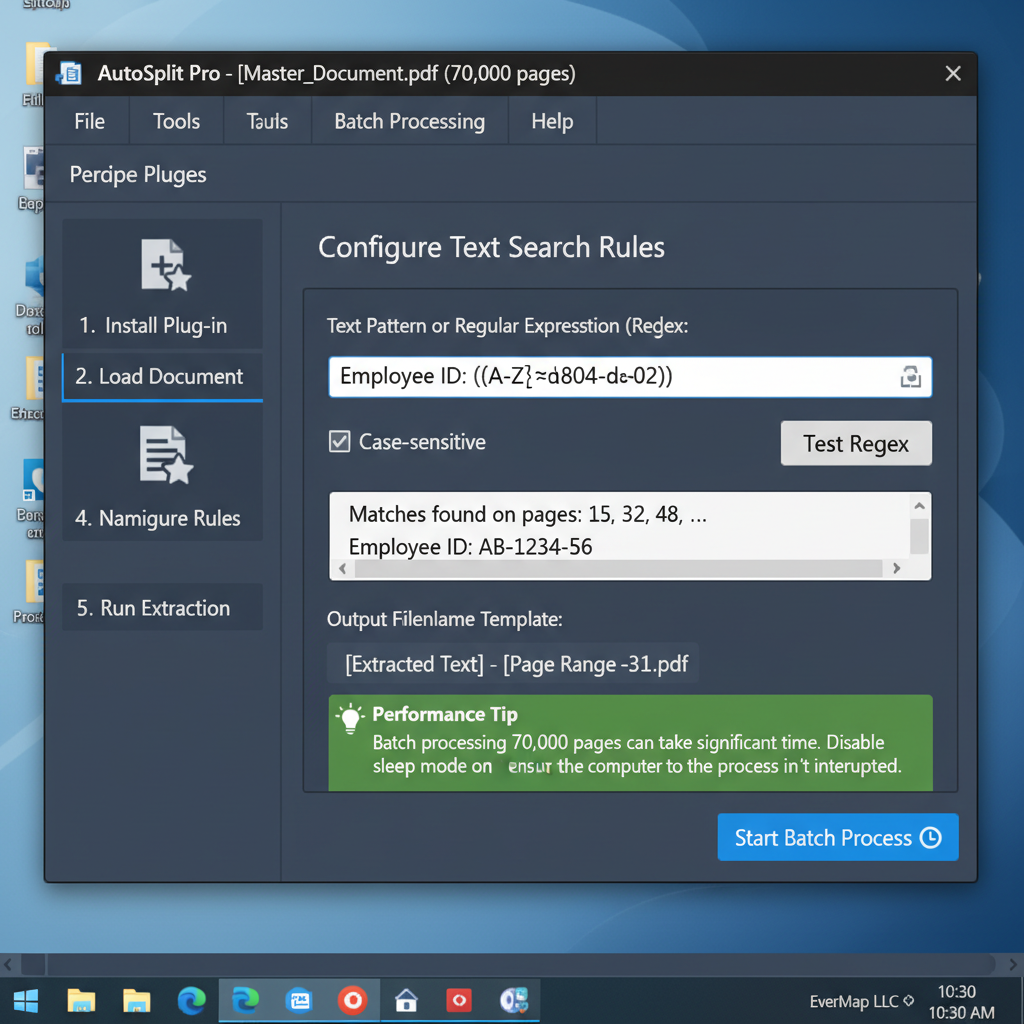
Processing tens of thousands of pages using standard PDF JavaScript often leads to application freezes or out-of-memory errors. Utilizing a specialized tool, such as AutoSplit by EverMap or a similar text-based extraction standalone app, is the most reliable approach.
These tools are specifically designed to scan large files for text patterns (like regex for Employee IDs), group the pages, and automatically apply the extracted text to the output filenames without crashing.
Download and install a text-based PDF splitting plug-in or standalone software compatible with your current PDF editor.
Open the 70,000-page PDF file within the software and navigate to the newly installed plug-in's batch processing menu.
Set the extraction parameters by defining the text format or regular expression (regex) that matches the Employee ID format.
In the output settings, select the option to use the extracted text (the Employee ID) as the automatic file name for the separated documents.
Choose an empty destination folder on your local drive and start the batch splitting process.
Divide Document and Use Acrobat JavaScript
If purchasing a specialized tool is not an option, you can divide the master file into smaller chunks and run a custom JavaScript to extract and rename the pages.
Efficiently Split and Manage PDFs with WPS Office
WPS Office offers a lightweight, powerful PDF editor equipped to handle large documents smoothly. You can easily manage, split, extract, and organize your PDF pages without relying on complicated scripts or memory-heavy applications.
- 1. Open your PDF: Launch WPS Office and open your large PDF document within the WPS PDF tool.
- 2. Access the Page tools: Navigate to the 'Page' tab located on the top navigation ribbon.
- 3. Select the Split function: Click on 'Split PDF' to open the document separation settings dialog.
- 4. Configure split settings: Choose your preferred splitting method (by page count, file size, or custom page ranges) to break down the large document.
- 5. Export the files: Select your desired output folder and click 'Split' to generate the new, manageable PDF files.

Frequently Asked Questions
Why does Acrobat JavaScript fail on a 70,000-page PDF?
Acrobat JavaScript operations consume significant memory. Iterating through 70,000 pages to run text-recognition and file-saving commands typically exceeds internal application memory limits, causing it to freeze or crash.
Can I use regular expressions to find employee IDs for splitting?
Yes. Most specialized PDF splitting plug-ins and custom JavaScripts support regular expressions (regex). This allows you to accurately identify specific formatting patterns, such as a 7-digit number, to locate the employee ID across thousands of pages.
What is the best way to rename PDF outputs automatically?
The most efficient way is to use a batch processing tool or PDF plug-in that supports text-pattern extraction. These tools allow you to specify a text zone or regex pattern, extract that specific text, and assign it as the output filename dynamically during the split process.


