

Fix Gibberish Text When Editing a PDF in Adobe Acrobat Pro

Question details
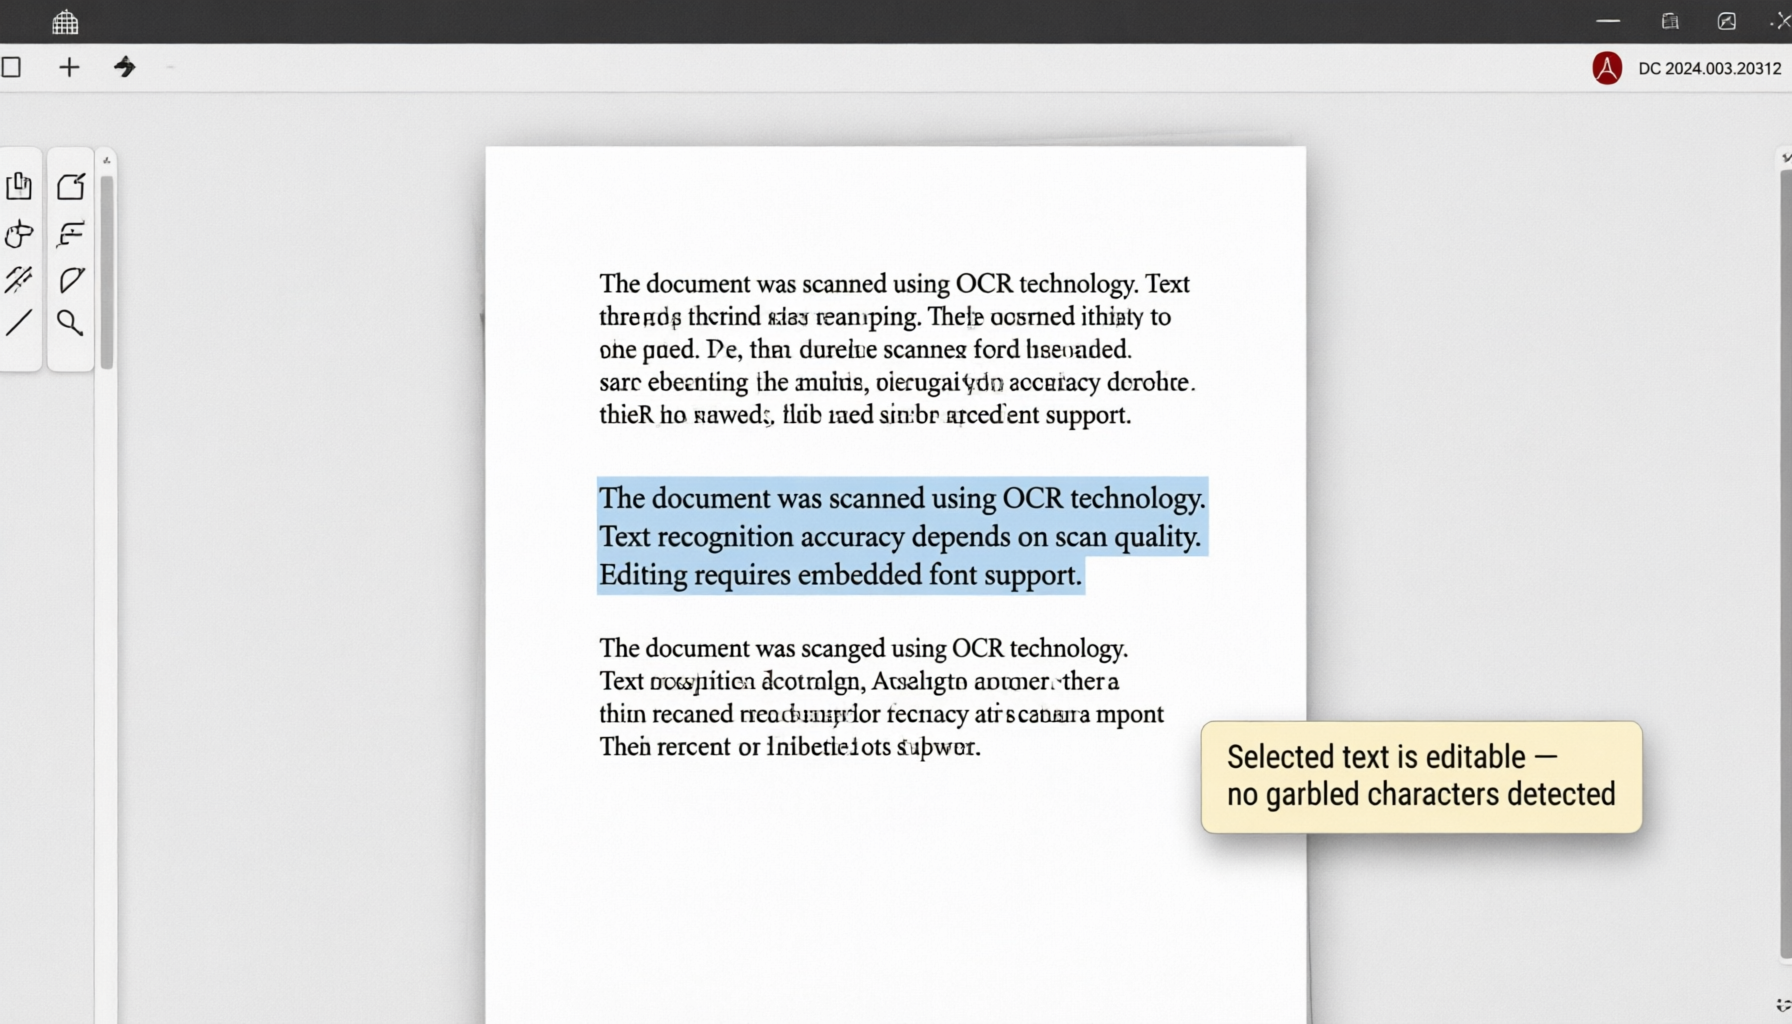
The user needs to edit PDF text in Acrobat Pro without it changing into unreadable characters.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- The user selects a text block for editing in a PDF that may have been scanned or processed with OCR.
- Observed behavior
- The selected text changes into gibberish. Undoing ClearScan or OCR restores the original appearance.
Check whether the PDF originated from a scan and identify the language used in the document. If possible, locate the original scan or source document so you can work from it instead of an incorrectly recognized text layer.
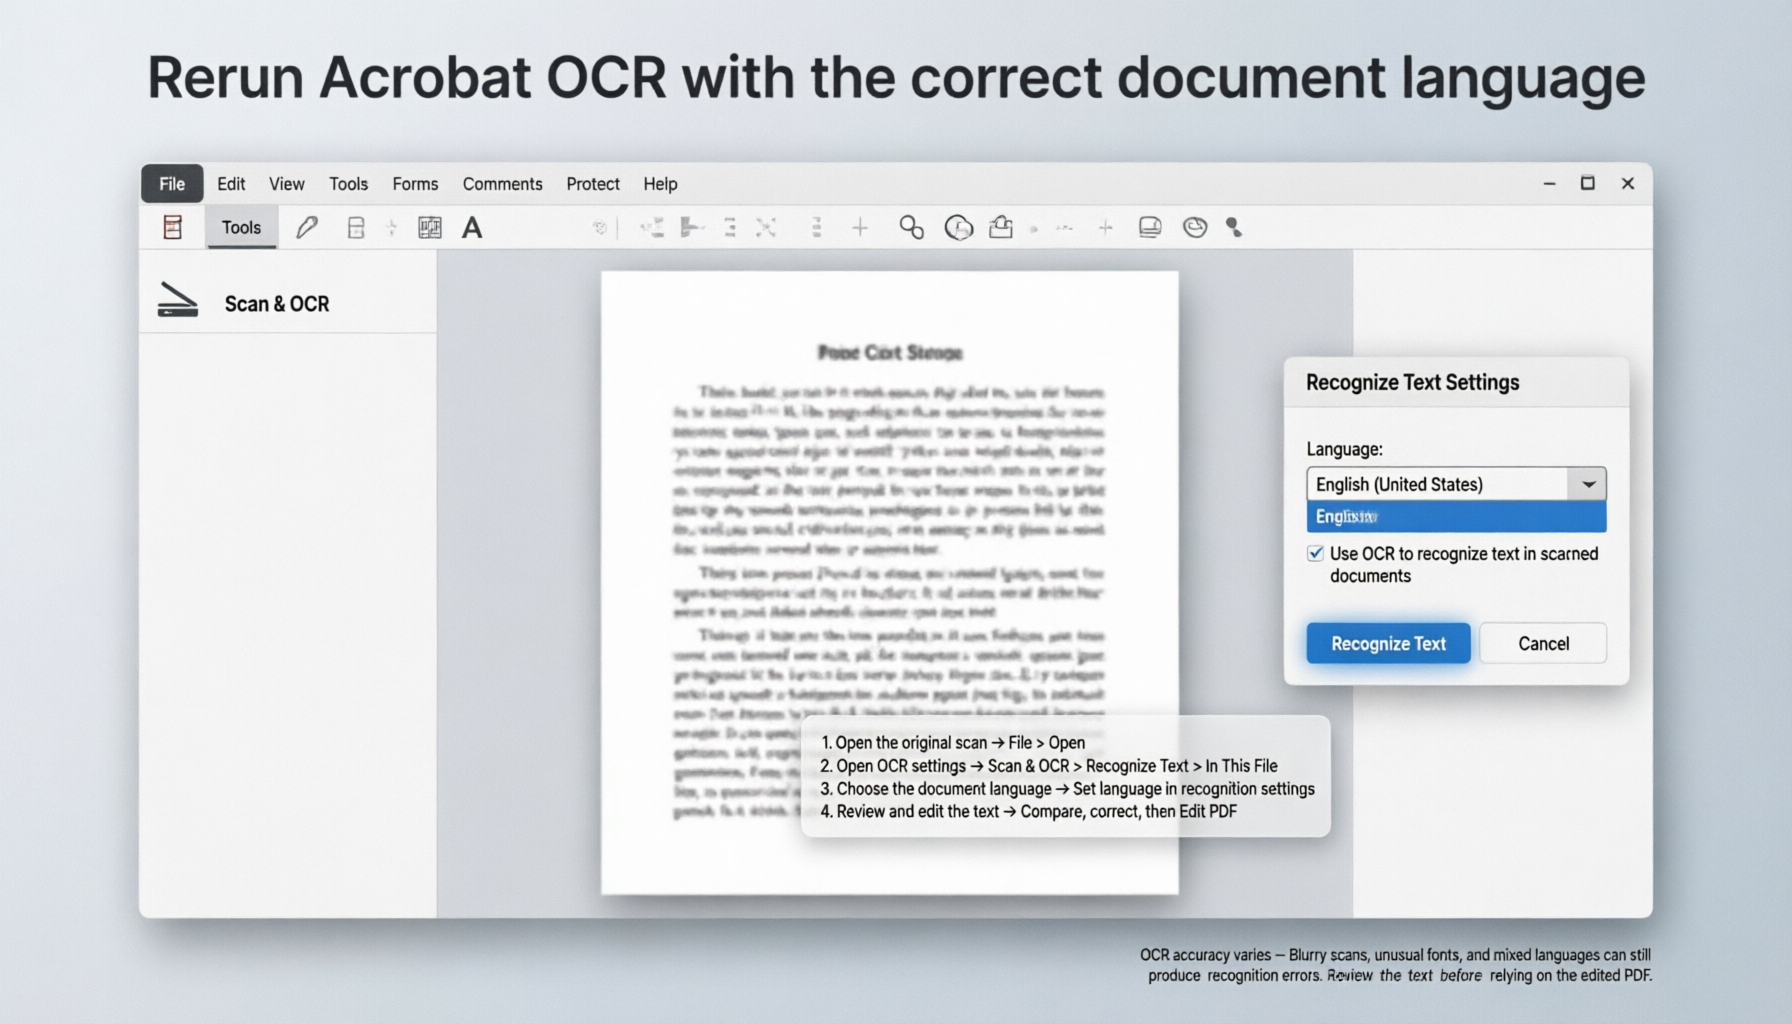
Rerun Acrobat OCR with the correct document language
Use this approach when a scanned PDF has an inaccurate OCR text layer.
In Acrobat Pro, choose File > Open and select the original scanned PDF, if available. Otherwise, undo the OCR operation that caused the problem.
Open Scan & OCR, select Recognize Text > In This File, and open the settings for text recognition.
Set the recognition language to the language used in the scan, then select Recognize Text. Menu labels may vary by Acrobat version.
Compare the recognized text with the scan, correct any errors, and then select Edit PDF to check whether the text can be edited normally.
Recreate the PDF from the source document or page image
Try this if OCR still produces gibberish or the PDF has a damaged source or unusual fonts.
Recognize and edit scanned PDF text in WPS Office
Use WPS PDF's OCR tools to recognize text in a scanned document, review the result, and make corrections. OCR and editing features may require a subscription or vary by version.
- 1. Open the scan: Open WPS Office, select Open, and choose the original scanned PDF.
- 2. Start OCR: In the PDF tools, select OCR and choose the relevant pages and document language if those options are available.
- 3. Review the recognized text: Run OCR and compare the result with the original scan. Correct any recognition errors in the editable output.
- 4. Save the result: Use File > Save As to save the corrected document in an available format, or export it as a PDF if needed.

Frequently Asked Questions
Why does PDF text become unreadable when I select it for editing?
A scanned PDF may contain an inaccurate OCR text layer, or the PDF may have a font or source-file problem. Try Scan & OCR > Recognize Text in Acrobat using the correct document language.
Can I undo OCR and try again?
If the OCR operation is still in your undo history, use Edit > Undo. Otherwise, open the original scan and run OCR again with the correct language.
What if the new OCR result is still wrong?
Check the scan's clarity and compare the recognized text with the original. If possible, export a new PDF from the source document, or create a PDF from a page image and run OCR again.
Is a password blocking my PDF signature related to the gibberish text?
A signing-password or permissions issue is separate from OCR text recognition. Check the document's security settings in Acrobat and contact the document owner if permission is needed.


