

Fix Strange Characters in PDF to Word Conversion

Question details
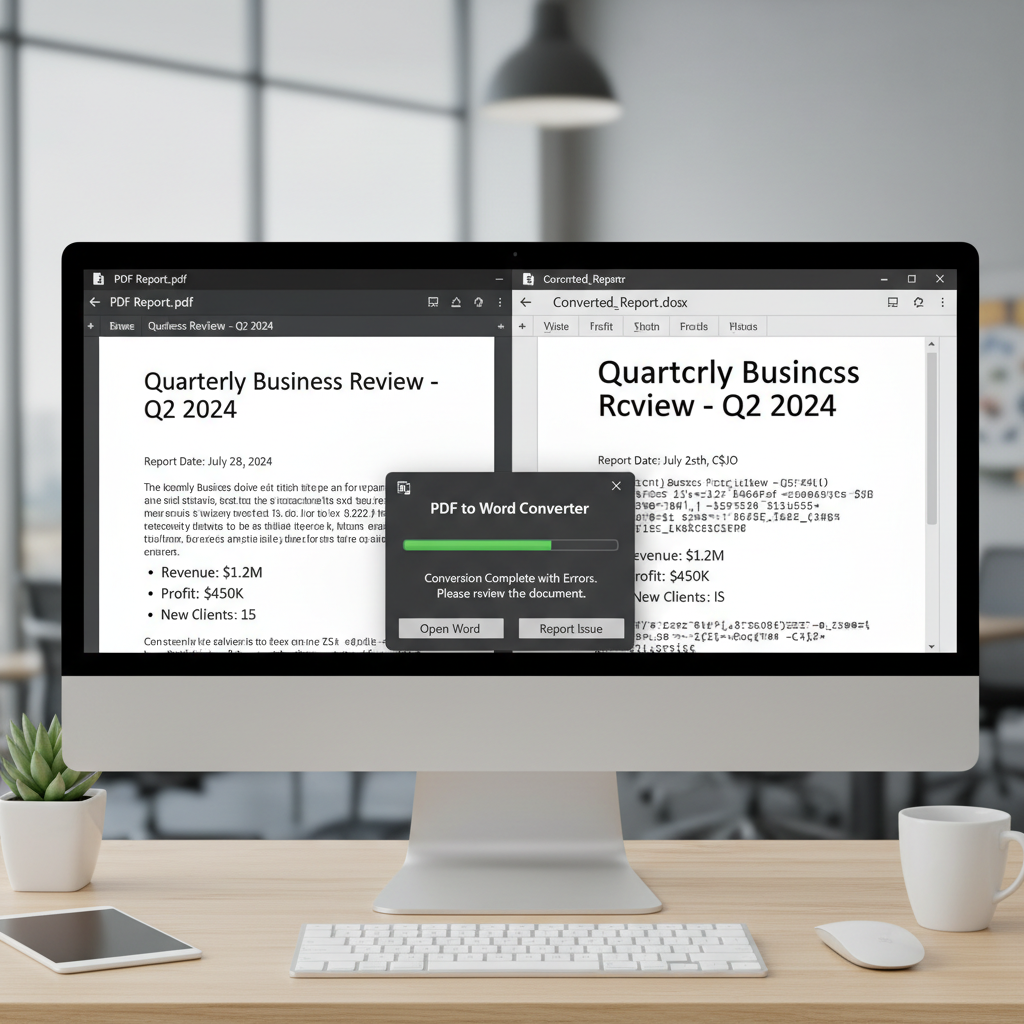
The user is experiencing weird or incorrect text characters after converting a PDF into a Word document.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF report into an editable Word document for updating or extracting information.
- Observed behavior
- The converted Word document contains odd text (such as "C$JO") and misinterpreted dates (changing "July 28" to "July 2sth") instead of the original readable text.
Verify whether your original PDF is a scanned document or uses non-standard embedded fonts, as these conditions commonly require specific OCR (Optical Character Recognition) language settings to convert accurately.
Adjust OCR Language Settings
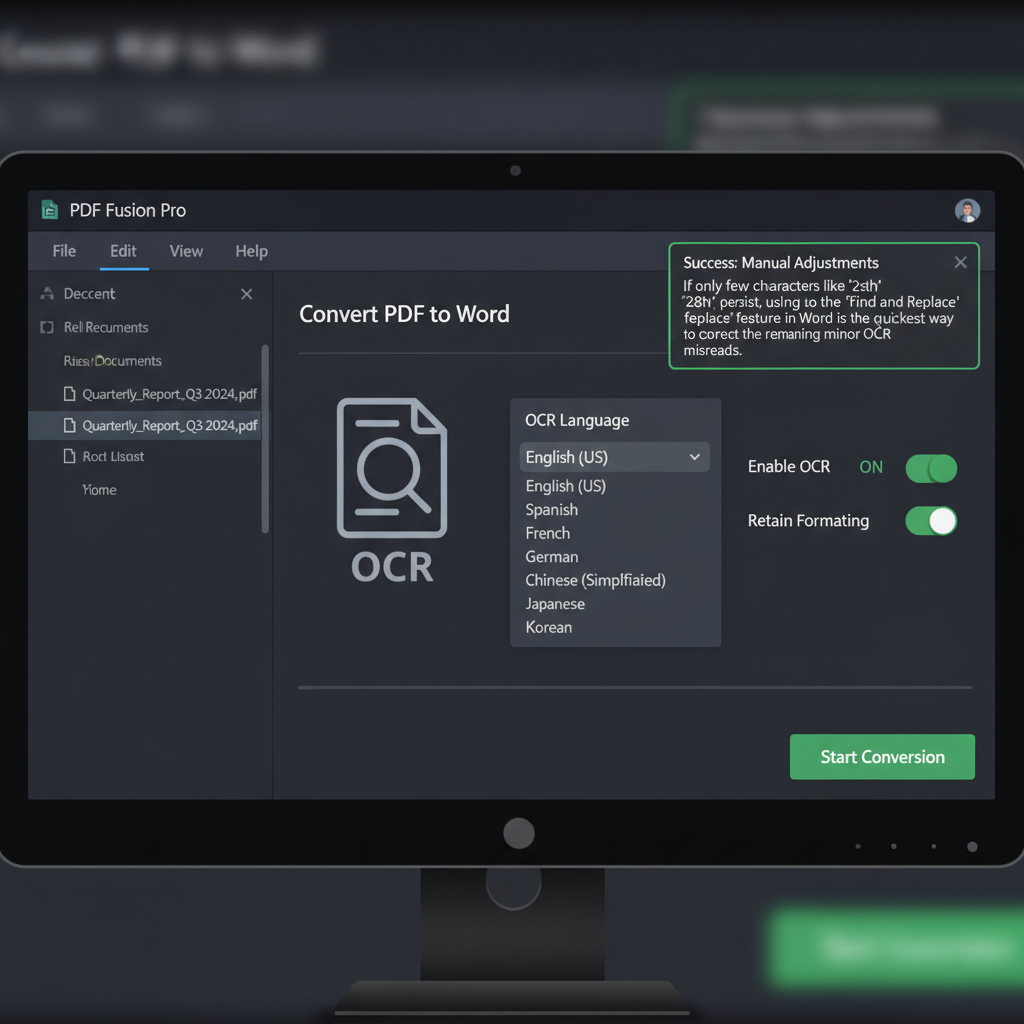
Selecting the correct document language before running the OCR conversion ensures the software correctly identifies letters and numbers instead of guessing strange characters.
When a PDF is an image or a scanned document, converters use OCR to "read" the shapes. If the OCR engine expects English but the text contains different characters or unusual stylistic fonts, it may output gibberish. Aligning the OCR settings with the source document resolves most character misinterpretation issues.
Open your PDF to Word conversion tool and look for the 'Settings', 'Preferences', or 'OCR Language' option before starting the conversion.
Set the recognition language to exactly match the primary language used in your source PDF report.
Start the conversion process again and review the newly generated Word document to verify that dates and text characters are now accurate.
Fix Font Encoding Issues by Flattening the PDF
If the original PDF used unusual or unembedded custom fonts, flattening the file by "Printing to PDF" forces the system to treat the text as standard images, which can then be accurately processed by OCR.
Convert PDF to Word Accurately with WPS Office
WPS Office features an advanced PDF to Word converter equipped with highly accurate OCR technology. It intelligently recognizes text, fonts, and layouts to prevent strange characters, ensuring your converted documents are pristine and ready to edit.
- 1. Open PDF to Word Tool: Launch WPS Office and select 'PDF to Word' from the main dashboard or the Tools tab.
- 2. Add Your PDF: Drag and drop the problematic PDF file directly into the conversion dialog box.
- 3. Configure OCR Settings: Ensure OCR is enabled and select the correct document language to guarantee precise character recognition.
- 4. Convert and Edit: Click 'Convert'. Once finished, WPS Office will automatically open the accurately formatted Word document for immediate editing.
Frequently Asked Questions
Why does copying text directly from a PDF sometimes paste as gibberish?
This happens when the PDF was created using a custom or subset font without a proper Unicode mapping table. The computer knows how to draw the physical shapes of the letters on the screen, but it does not know what actual text characters those shapes represent, resulting in gibberish when copied or converted.
Can I fix strange characters without converting the PDF all over again?
Yes. If the conversion is mostly accurate and only specific repeating characters are strange (for instance, the number '8' turning into an 's'), you can open the document in Word and use the 'Find and Replace' tool (Ctrl + H) to replace the misread characters quickly across the entire document.
Does the quality of the original PDF affect the conversion accuracy?
Absolutely. Low-resolution scans, handwritten text, heavy watermarks, and complex background colors can easily confuse the OCR engine. Using clear, high-resolution PDFs with standard contrast significantly reduces the chance of getting strange characters during conversion.


