

How to Extract Text After Keywords from an OCR PDF

Question details
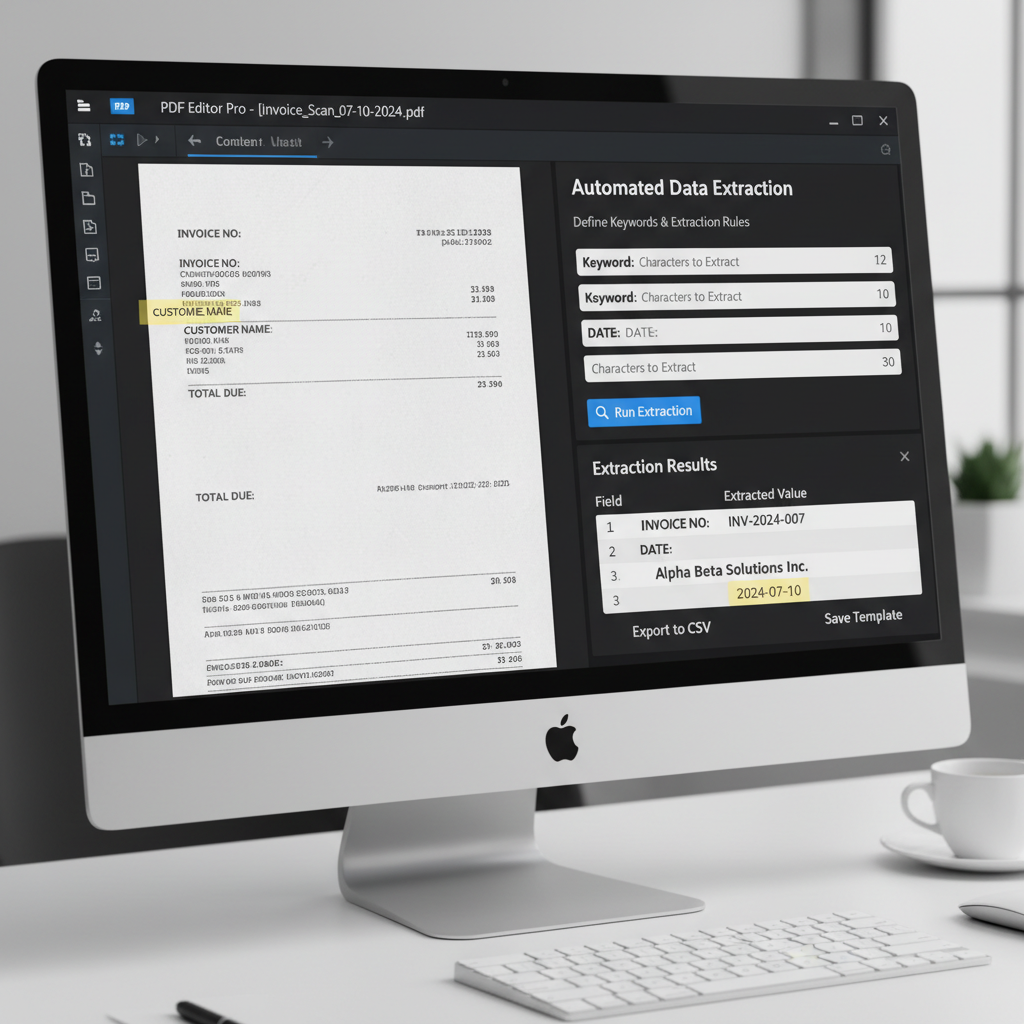
The user wants to automatically find specific keywords in a scanned or OCR-processed PDF and extract the characters or text immediately following those keywords for export.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Processing scanned documents to systematically pull specific data points (like invoice numbers, names, or values) located right after standard text keywords.
- Observed behavior
- The user needs an automated way to search for keywords and extract a fixed number of following characters, which natively requires scripting or external automation tools.
Ensure your scanned PDF has already been processed with OCR (Optical Character Recognition) so that the text is selectable and searchable. Without OCR, the document acts as a flat image and automated text extraction will fail.
Use Acrobat JavaScript or PDF Automation Scripts
For exact and scalable automation, using custom scripts is the most robust method to find keywords and pull the subsequent text.
Standard PDF readers cannot automatically extract relational text data without custom code. By utilizing Acrobat JavaScript, Python libraries (like pdfplumber or PyPDF2), or desktop automation software, you can programmatically search the document, define text boundaries, and export exactly what you need.
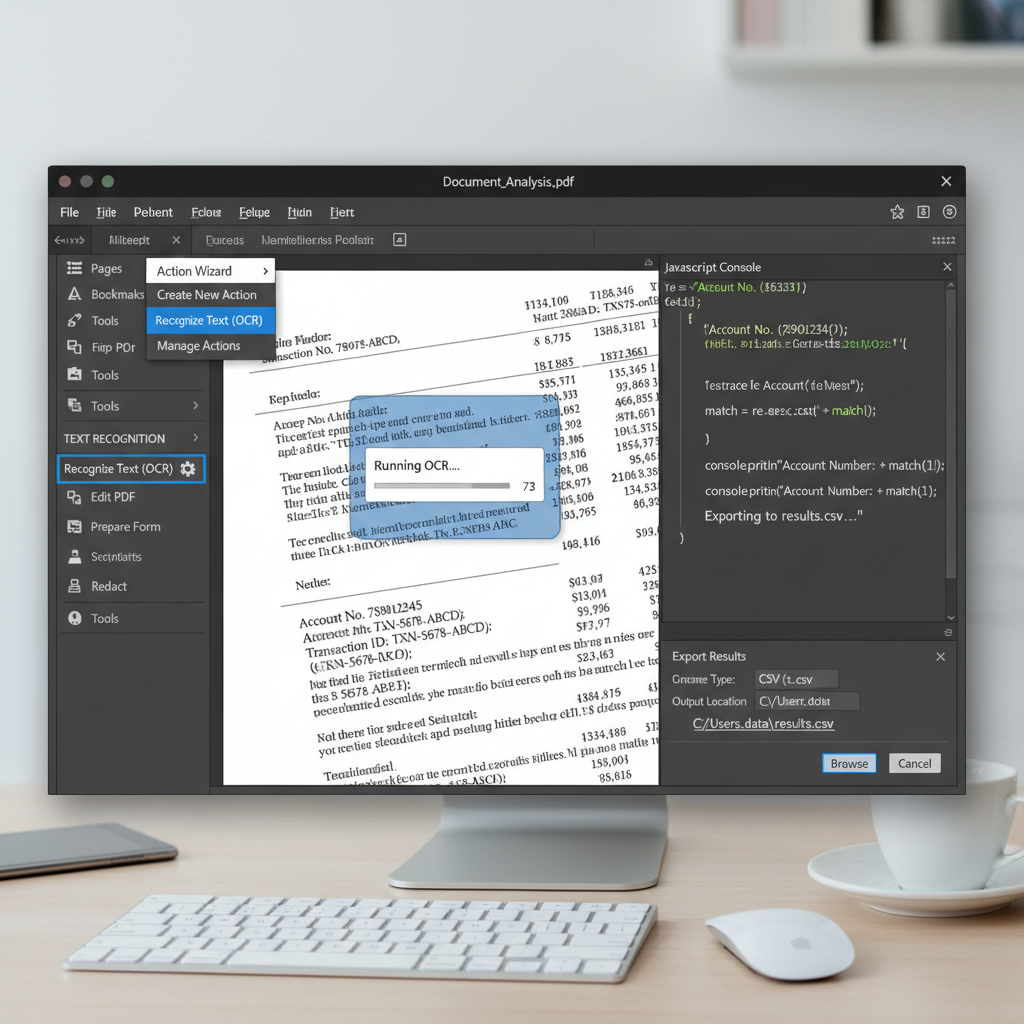
Open your PDF in an advanced PDF editor and run the 'Recognize Text' or OCR tool to make all scanned text searchable.
Open the JavaScript console or Action Wizard in your PDF editor, or set up a Python script using a PDF processing library.
Create a script utilizing Regular Expressions (Regex) to search for your target keyword, define the extraction boundaries (e.g., the next 15 characters or until the next line break), and capture the resulting string.
Program the script to append or output the extracted strings into a CSV, text file, or spreadsheet format for final use.
Convert PDF to Excel for Easy Filtering (No-Code Workaround)
If you do not know how to code, converting the OCR PDF to Excel allows you to use standard spreadsheet formulas to extract text after keywords.
Use WPS PDF to OCR and Convert Files for Data Extraction
WPS Office includes a powerful PDF toolkit that performs highly accurate OCR on scanned documents and instantly converts them to Excel or Word. This allows you to extract specific text after keywords easily using standard spreadsheet formulas, without needing complex scripting knowledge.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Run the OCR Tool: Navigate to the 'Tools' tab and click on 'OCR' to extract selectable text from the scanned images.
- 3. Convert to Excel: Click 'PDF to Excel' on the toolbar to export the recognized text into a structured spreadsheet.
- 4. Extract Data using Formulas: Open the converted file in WPS Spreadsheet and use text formulas to easily pull the characters immediately following your keywords.

Frequently Asked Questions
Can standard PDF readers automatically extract specific data fields?
No, standard PDF readers can search for text but do not have built-in features to automatically extract and export specific characters following a keyword. Accomplishing this requires advanced scripting, or converting the document into a spreadsheet format first.
What is OCR and why is it necessary for PDF text extraction?
OCR (Optical Character Recognition) converts images of typed or handwritten text into machine-encoded text. It is mandatory for scanned PDFs because, without it, the computer only reads the document as a flat image and cannot identify, search for, or extract keywords.
Can I extract text from a PDF without any programming knowledge?
Yes, the easiest non-programming method is to convert the PDF to a Word document or Excel spreadsheet using tools like WPS Office. Once converted, you can use standard search features or spreadsheet text formulas to filter and extract the required data.
What programming languages are best for automating PDF text extraction?
Python is highly recommended due to powerful libraries like PyPDF2, pdfplumber, and PyMuPDF which handle text parsing well. Acrobat JavaScript can also be used directly within Adobe Acrobat for internal document processing and automation.


