

How to Fix Acrobat OCR Working Only on Some Scanned Pages

Question details
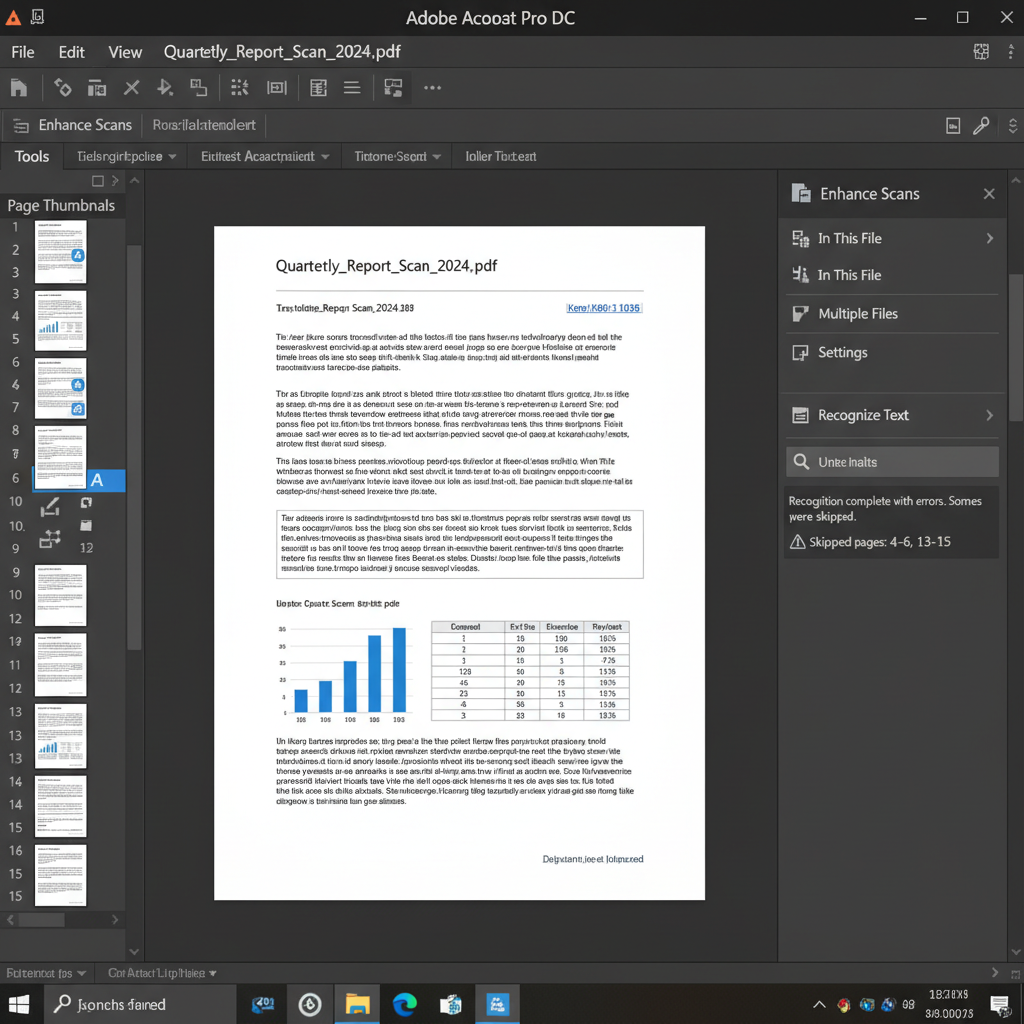
The user needs to resolve an issue where the software's text recognition function fails to process all pages of a scanned document evenly.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Using the Optical Character Recognition (OCR) feature to convert a multi-page scanned PDF document into readable and searchable text.
- Observed behavior
- The OCR tool successfully recognizes text on some pages but skips others, even though the skipped pages appear visually clear and readable.
Ensure you have a backup copy of your original scanned PDF document before making any changes, and verify your internet connection if you plan to update your software.
Verify File Integrity and Update Acrobat
Check if the issue is isolated to a specific PDF and ensure your software has the latest patches installed.
Software bugs or file-specific structural issues can prevent text recognition from completing. Testing a different file and updating the application are the best first steps.
Open a completely different scanned PDF in your application and run the OCR tool. If it successfully recognizes all pages, the issue is likely specific to the structure or hidden layers of your original file.
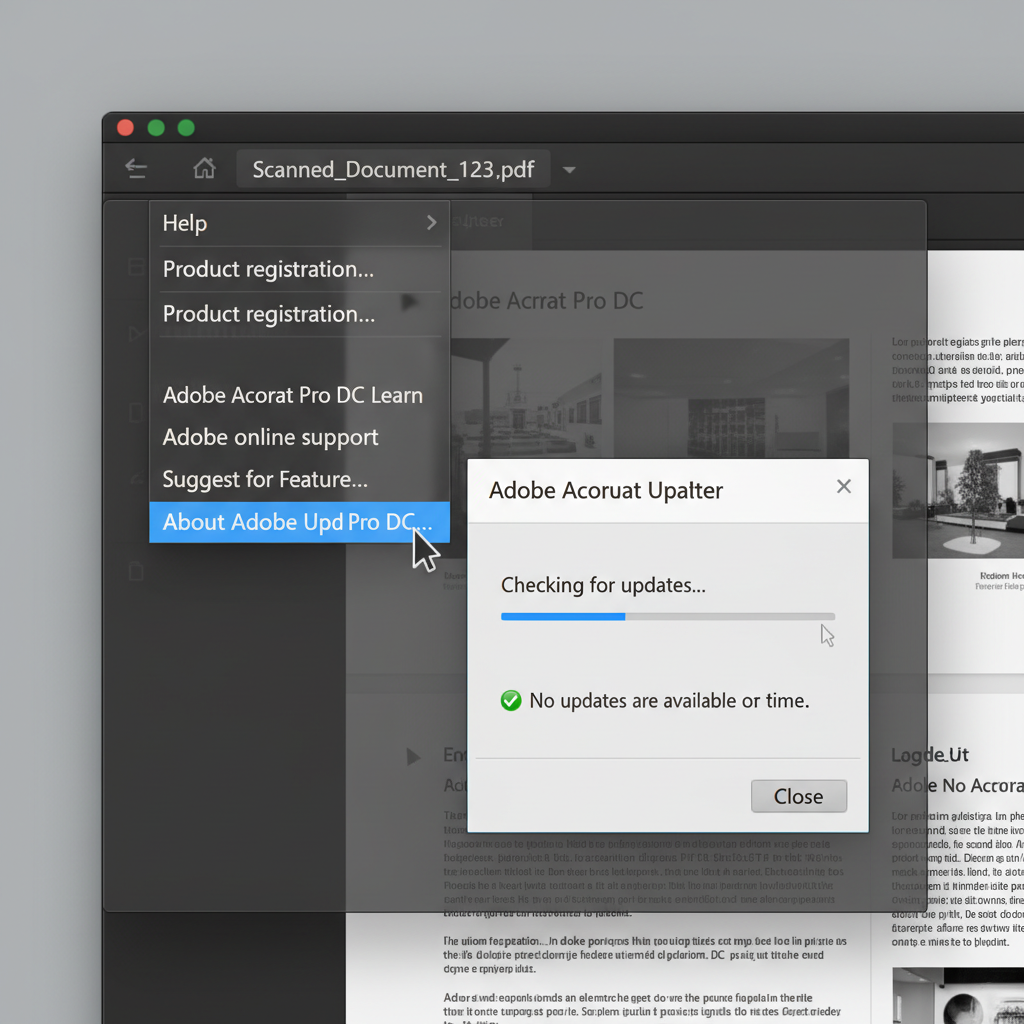
Click on 'Help' in the top menu bar of Adobe Acrobat and select 'Check for Updates'. Follow the on-screen prompts to download and install any available updates.
Once the update is complete, close the application entirely and restart your computer to ensure the updates are properly applied before trying the OCR tool again.
Reset Application Preferences to Default
Corrupted preference settings can sometimes interfere with advanced functions like text recognition.
Create a New Administrator User Profile
System permission issues or corrupted user profiles on your operating system can restrict application functionalities.
Use WPS Office to Reliably Extract Text from Scanned PDFs
If your current PDF reader continues to skip pages during text recognition, WPS Office offers a highly accurate and stable PDF OCR tool to convert your scanned documents into editable text seamlessly.
- 1. Open your PDF in WPS: Launch WPS Office, select 'PDF' from the home screen, and open the scanned document you want to process.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon menu and click the 'OCR' button.
- 3. Configure output settings: Choose your desired output method, such as extracting text directly or converting the entire document to a Word file, and select the language of the document.
- 4. Start recognition: Click 'Start' to begin the process. WPS Office will systematically scan and recognize text across all pages reliably.

Frequently Asked Questions
Why does OCR sometimes fail on clear scanned pages?
OCR failure on visually clear pages can occur due to hidden formatting layers, unusual embedded fonts, subtle background noise, or a document structure issue that confuses the text recognition engine.
Can image resolution affect PDF OCR performance?
Yes. While images may look readable to the human eye, resolutions below 300 DPI or extremely high resolutions can sometimes cause OCR engines to misinterpret or skip text entirely.
How do I know if my OCR issue is file-specific?
Test the OCR feature on a different scanned PDF document. If the software processes the other document perfectly, the problem is likely isolated to the original file's metadata, image encoding, or structure.


