

How to Deskew Scanned PDFs Without Losing OCR Text Accuracy

Question details
The user wants to straighten scanned PDF pages without degrading the quality of the exact hidden OCR text layer.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- Processing scanned documents to correct skewed angles while maintaining highly accurate, searchable text overlays.
- Observed behavior
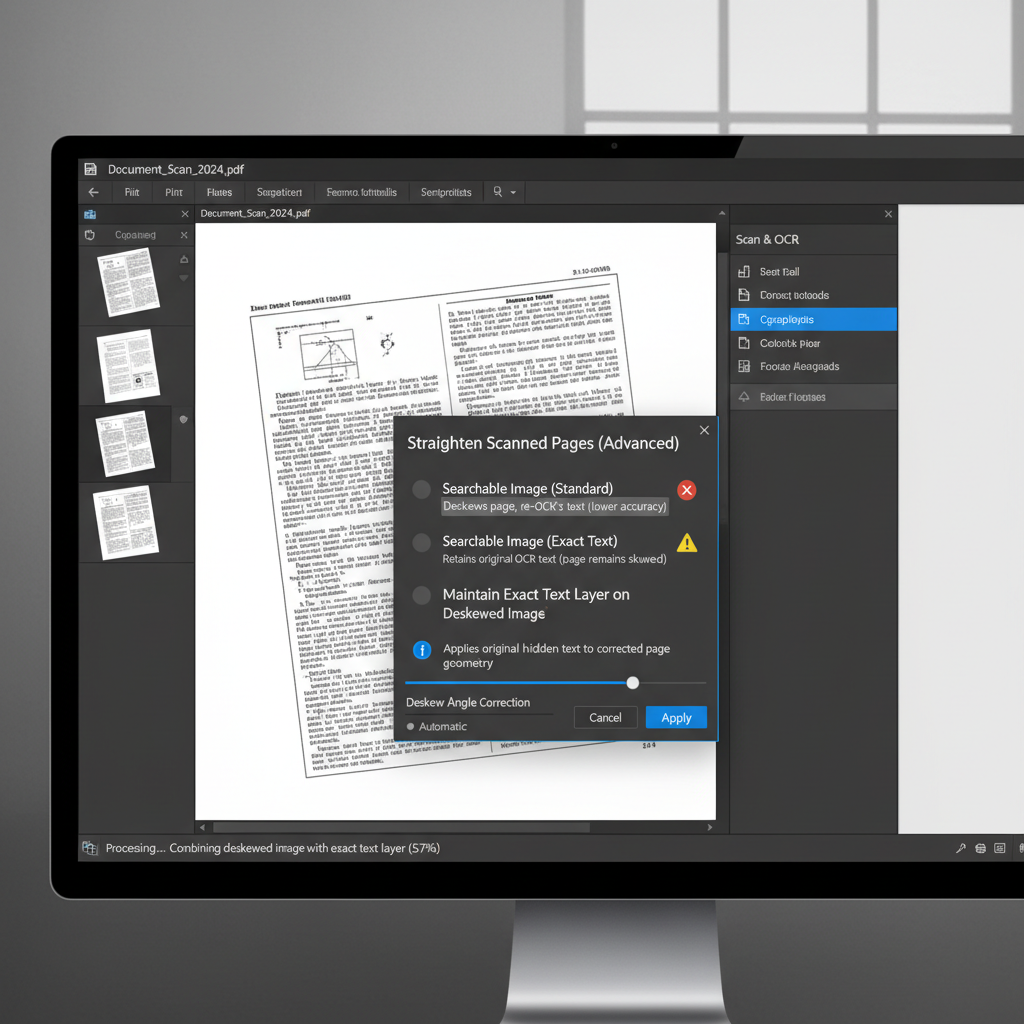
- Standard 'Searchable Image' modes deskew the page but lower OCR quality, whereas 'Searchable Image (Exact)' keeps high text accuracy but leaves the page skewed. There is no native command to transfer the exact text layer to a separately deskewed image.
Create a backup copy of your original scanned PDF, as running OCR multiple times or altering the page geometry can permanently change the document structure.
Deskew the Image Before Applying OCR
Because PDF editors process text and images using conflicting methods during OCR, the most reliable approach is to physically straighten the document before running the text recognition process.
Software like Adobe Acrobat does not currently provide a simple command to copy an exact hidden text layer and paste it onto a separately deskewed background. To get both a straight page and perfect text, you must separate the two tasks.
Open your original, un-OCRed scanned file in a dedicated document-processing tool or image editor.
Apply the software's 'Deskew' or 'Straighten' function to align all pages perfectly vertically, making sure not to downsample the image resolution.
Export or save the corrected, straightened document as a new PDF file.
Open the new, straight PDF in your preferred PDF editor, navigate to the OCR tool, and run it using the highest quality settings available.
Use Advanced OCR Settings in PDF Software
Adjust your PDF editor's built-in OCR settings to prevent image downsampling during the deskewing process.
Easily Extract and Manage OCR Text with WPS PDF
WPS Office includes a powerful PDF toolkit equipped with advanced OCR capabilities. It allows you to accurately recognize and extract text from scanned documents while maintaining image clarity.
- 1. Open the PDF: Launch WPS Office and open your scanned PDF document in WPS PDF.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR'.
- 3. Configure output settings: Select the document language and choose whether you want to extract the text to a separate document or create a searchable PDF.
- 4. Start Recognition: Click 'Convert' or 'Extract' to process the document. WPS will intelligently recognize the text layers while preserving formatting.

Frequently Asked Questions
Why does deskewing sometimes ruin my OCR text accuracy?
When PDF software automatically deskews a page, it often applies compression or downsampling to the background image to save file size. This reduction in image resolution makes the letter shapes blurry, causing the subsequent OCR process to generate weaker, less accurate text.
Can I extract the exact text layer and apply it to a newly straightened PDF?
No, standard PDF editors do not currently support copying the hidden OCR text layer and pasting it perfectly over a separately processed or straightened background. You generally need to run the OCR process from scratch on the newly straightened image.
What resolution is best for scanning documents intended for OCR?
For optimal OCR accuracy, it is highly recommended to scan documents at 300 DPI (dots per inch) or higher. Lower resolutions do not provide enough pixel density for the software to accurately distinguish between complex letter shapes.


