

How to OCR a Greek Scanned PDF and Export to Word

Question details
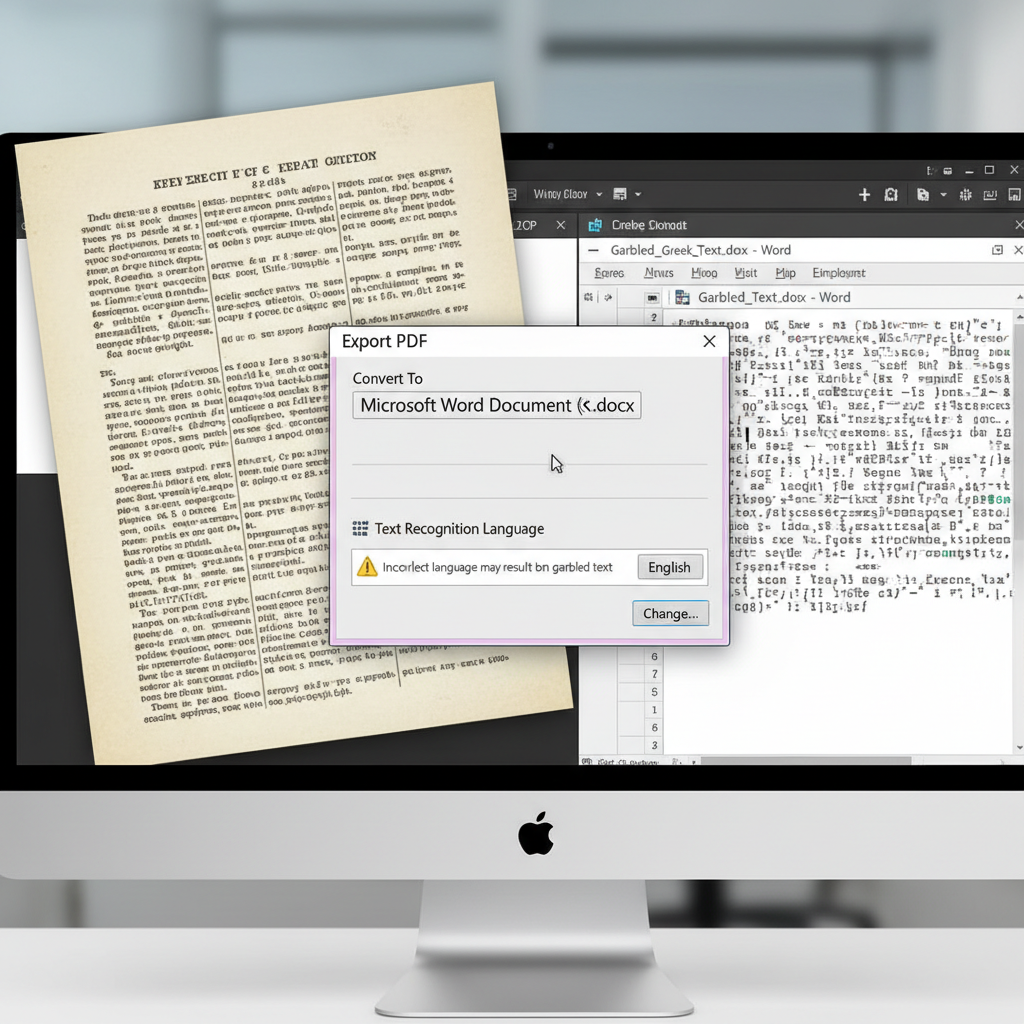
The user needs to extract Greek text from a scanned PDF using OCR and export it to a Microsoft Word document without encountering unreadable symbols or garbled characters.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF containing Greek text into an editable Word document.
- Observed behavior
- If the correct OCR language is not set, the exported Greek text may appear as unreadable symbols or incorrect characters in Microsoft Word.
Ensure that the scanned PDF is legible and clearly captures the text, as poor scan quality, low resolution, and unusual font encodings can significantly reduce OCR accuracy regardless of the language settings.
Configure OCR and Export Settings in Adobe Acrobat
Use Acrobat's built-in Scan & OCR tool alongside the Export PDF feature, specifically setting the recognition language to Greek.
When dealing with non-English text like Greek, the OCR engine must be explicitly told which language to look for. Failing to set this will result in the software trying to match Greek letters to English characters, producing garbled text.
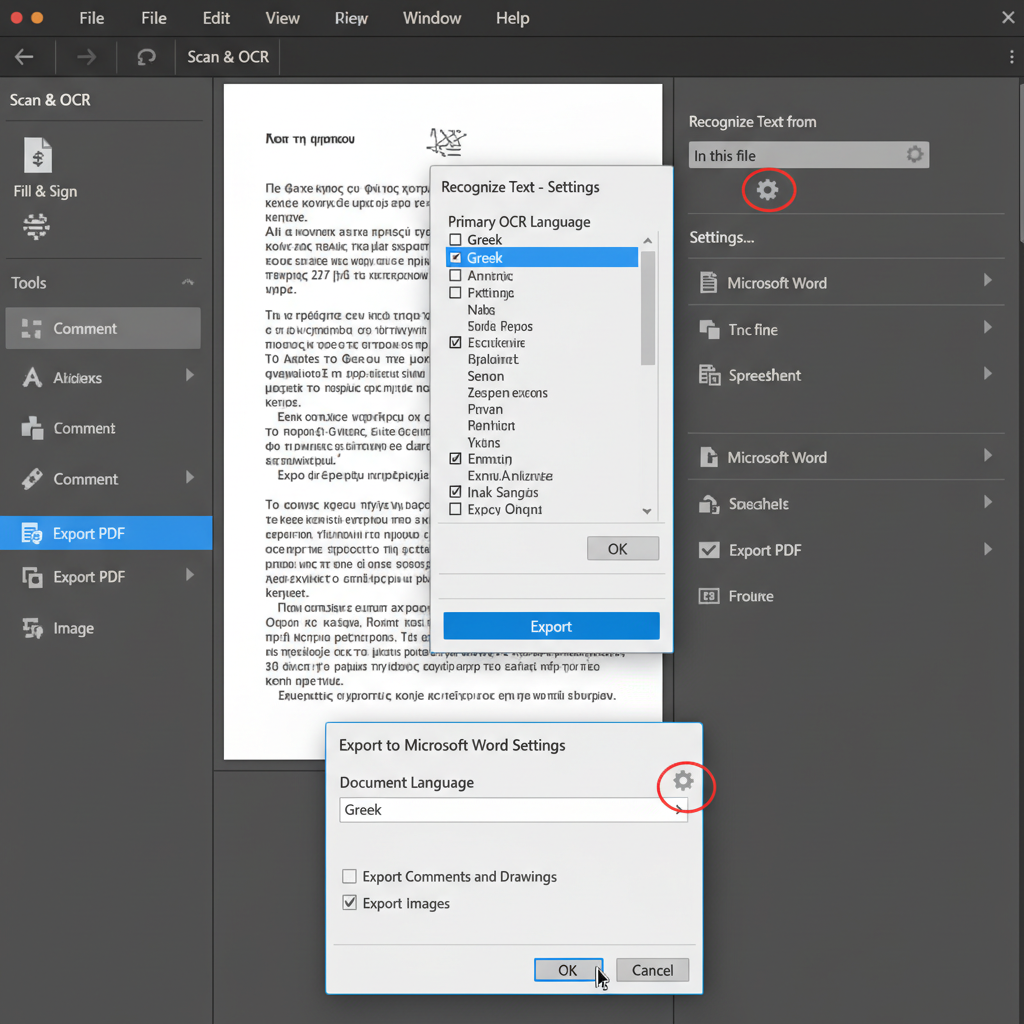
Open the scanned PDF in Adobe Acrobat. Navigate to the 'Scan & OCR' tool and explicitly select 'Greek' as the recognition language to process the text.
Go to the 'Tools' menu at the top, select 'Export PDF', and choose 'Microsoft Word' as your output format.
Click the 'Settings' gear icon next to the Word option. Click 'Set Language', scroll to find and select 'Greek', and then click 'OK'.
Click the 'Export' button, choose your save location, and save the file as a Word document.
Extract Text from Scanned PDFs with WPS Office
WPS Office offers a powerful, built-in OCR feature that effortlessly recognizes text from scanned PDFs and converts them into highly compatible, editable Word documents.
- 1. Open the Scanned PDF: Launch WPS Office and open your scanned PDF file.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button, or choose 'PDF to Word' from the menu.
- 3. Select the Document Language: In the OCR settings prompt, ensure you select the correct language corresponding to your document to guarantee accurate text extraction.
- 4. Convert to Word: Click 'Convert' or 'Extract' to generate an editable Word document with your accurately recognized text.

Frequently Asked Questions
Why does my Greek PDF export to Word with garbled text?
This usually happens when the OCR engine defaults to English or another incorrect language. You must explicitly set both the OCR recognition language and the document export language to Greek before converting.
Can I improve the OCR accuracy of a scanned PDF?
Yes, you can improve accuracy by ensuring the original scan is high resolution (at least 300 DPI), the text is not skewed, and the lighting is even. Setting the exact recognition language also vastly improves results.
Does WPS Office support OCR for different languages?
Yes, the OCR feature in WPS Office supports multiple languages. When using the OCR tool, you can select the specific language of your document to ensure the extracted text is accurate and readable.


