

Fix Unsearchable PDF Text After Adding a Header from Google Docs

Question details
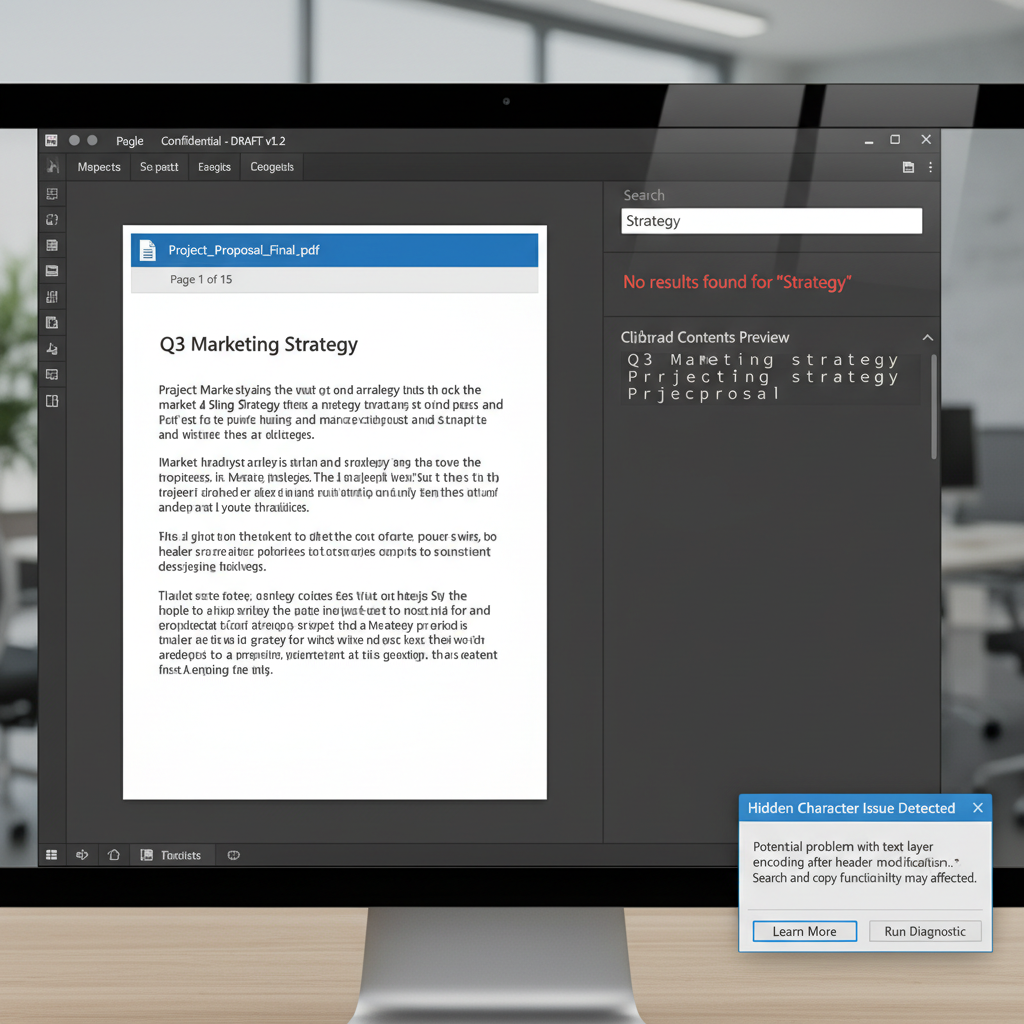
The user needs to resolve an issue where the text in a PDF becomes unsearchable and produces garbled results when copied, which occurs specifically after adding a header to a document that was originally created in Google Docs.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- Modifying a PDF originally created from Google Docs by adding a header, then attempting to search for keywords or copy text to the clipboard.
- Observed behavior
- The PDF looks visually correct when viewed or printed, but the text layer contains hidden spaces. Searching for words fails, and copied text pastes as separated or garbled characters.
Ensure you have access to the original source document (such as the Google Docs file) if possible, as modifying the source file is often the most reliable way to prevent PDF text layer corruption.
Export Directly as PDF from Google Docs
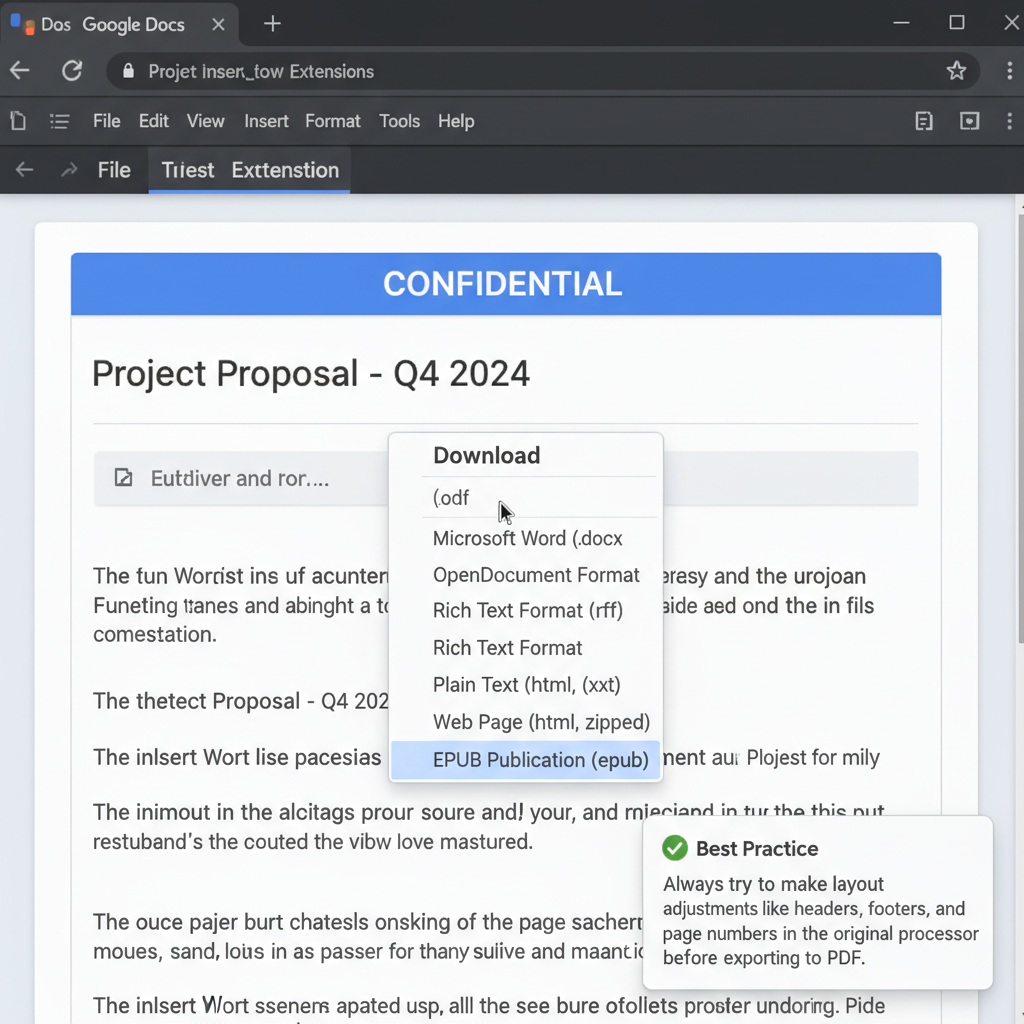
The most effective way to prevent text layer corruption is to avoid the Print to PDF function and use the native download feature in Google Docs.
When you use a system print dialog to create a PDF from a browser, the resulting text layer can be fragile. Adding a header later with a PDF editor can misalign the character encoding. Exporting natively ensures the text layer remains intact.
Open your original document inside Google Docs in your web browser.
Navigate to the Insert menu, select Headers & footers, and add your required header directly within Google Docs.
Click on File in the top menu, hover over Download, and select PDF Document (.pdf) from the dropdown list to save the file to your device.
Use OCR to Rebuild the PDF Text Layer
If you cannot access the original Google Docs file and only have the corrupted PDF, you can use an Optical Character Recognition (OCR) tool to replace the damaged text layer.
Fix and Edit PDFs Seamlessly with WPS Office
WPS Office provides a powerful PDF editor that handles headers, footers, and OCR tasks without corrupting your text layers. It serves as a reliable all-in-one suite to prevent common PDF formatting issues.
- 1. Install WPS Office: Download and install WPS Office, then open your problematic PDF file in WPS PDF.
- 2. Add headers safely: Navigate to the 'Insert' tab and select 'Header and Footer' to safely append information to your document without breaking the text encoding.
- 3. Use OCR to fix garbled text: If the document text is already unsearchable, switch to the 'Tools' tab and click the 'OCR' button to extract and repair the damaged text layer.
- 4. Save your searchable PDF: Go to 'Menu' and click 'Save As' to store your newly optimized PDF, which will now have fully searchable and copyable text.

Frequently Asked Questions
Why does adding a header corrupt my PDF text?
In PDFs generated via a web browser's Print to PDF feature, the underlying text layer mapping can be fragile. When a third-party editor injects new objects like a header into this structure, it can misalign the character encoding map, causing hidden spaces or turning readable text into garbled symbols.
Can I fix the unsearchable text without using OCR?
If you do not want to use an OCR tool, the only dependable alternative is to return to the original source file (such as Google Docs or Microsoft Word), insert your header there, and perform a native 'Save as PDF' or 'Download as PDF' operation.
Does this issue affect scanned PDFs as well?
Generally, no. This specific issue usually affects digital text documents that were 'printed' to a PDF virtual printer. Scanned documents are essentially flat images that rely entirely on OCR for searchability, so adding a header does not disrupt a digital font character map.


