



How to Use Separate Excel Slicers with PivotTables from One Data Set

Question details
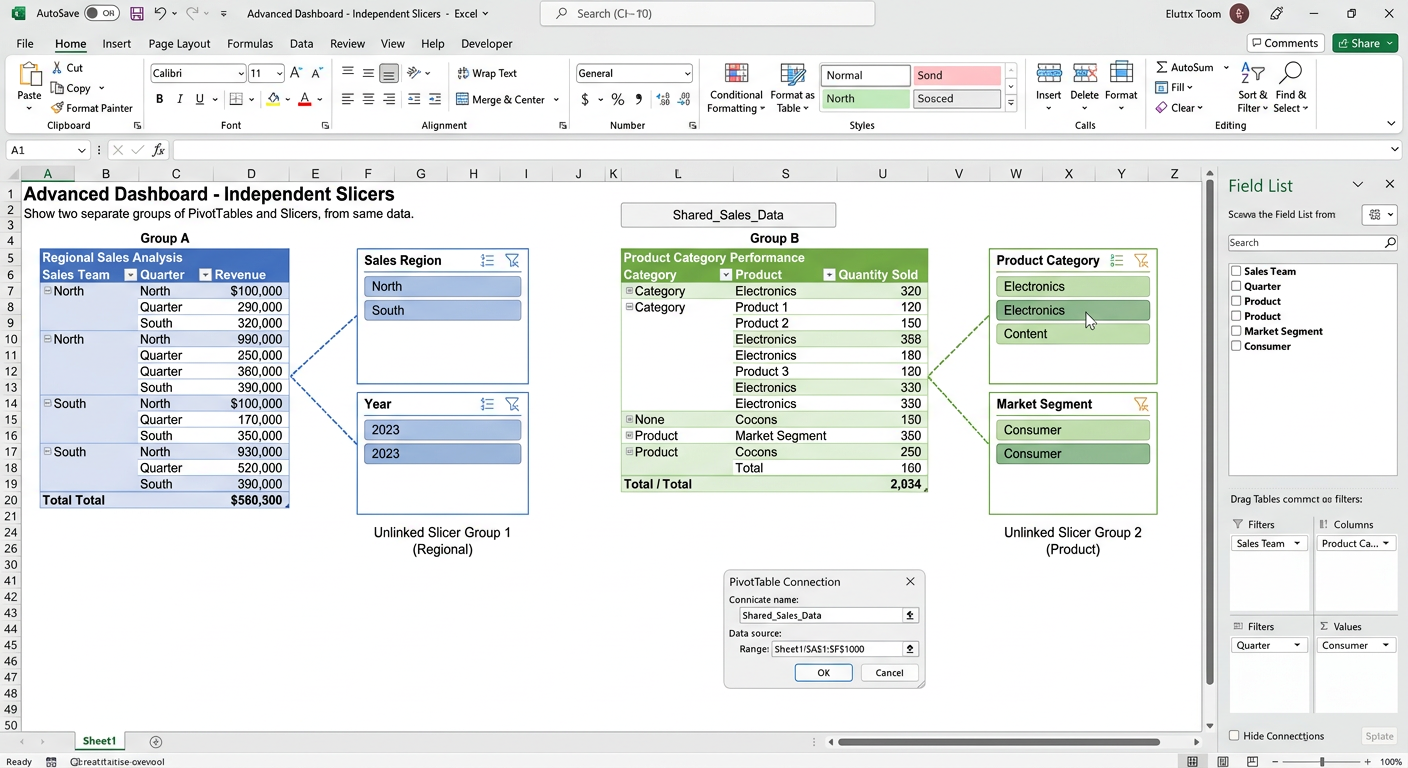
The user wants to know how to use separate slicers to independently control different groups of PivotTables that are all built from the same imported data source.
- Product
- Excel
- Device & OS
- not provided
- Scenario
- Creating complex interactive dashboards where different slicers need to act independently on specific PivotTables sourced from the exact same dataset.
- Observed behavior
- Slicers connected to PivotTables that share the same PivotCache or data model are linked by default, causing filtering actions on one slicer to unintentionally affect all related PivotTables.
Before you begin, check your existing slicer settings under 'Report Connections' to see if a simple uncheck will solve your issue, and ensure you save a backup of your file as creating independent PivotCaches may increase the overall workbook size.
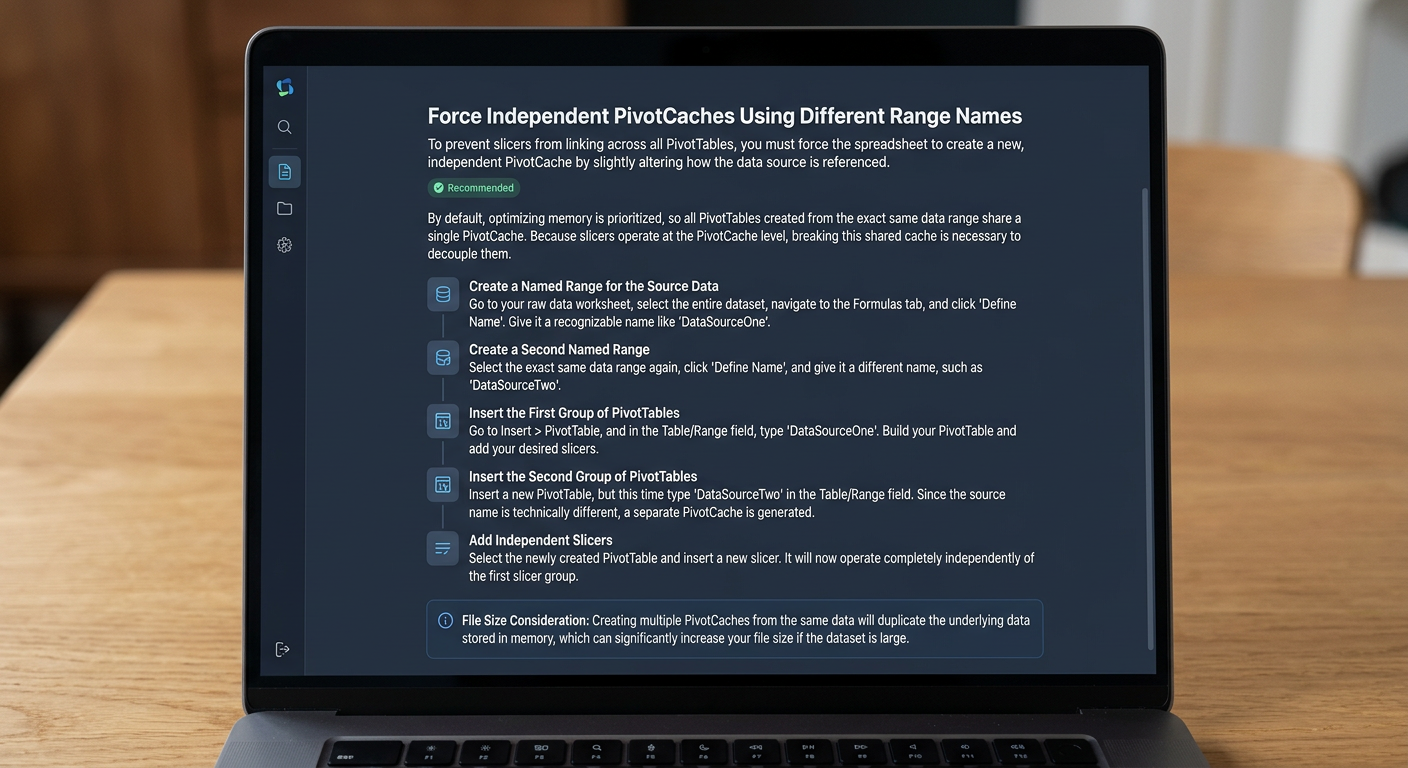
Force Independent PivotCaches Using Different Range Names
To prevent slicers from linking across all PivotTables, you must force the spreadsheet to create a new, independent PivotCache by slightly altering how the data source is referenced.
By default, optimizing memory is prioritized, so all PivotTables created from the exact same data range share a single PivotCache. Because slicers operate at the PivotCache level, breaking this shared cache is necessary to decouple them.
Go to your raw data worksheet, select the entire dataset, navigate to the Formulas tab, and click 'Define Name'. Give it a recognizable name like 'DataSourceOne'.
Select the exact same data range again, click 'Define Name', and give it a different name, such as 'DataSourceTwo'.
Go to Insert > PivotTable, and in the Table/Range field, type 'DataSourceOne'. Build your PivotTable and add your desired slicers.
Insert a new PivotTable, but this time type 'DataSourceTwo' in the Table/Range field. Since the source name is technically different, a separate PivotCache is generated.
Select the newly created PivotTable and insert a new slicer. It will now operate completely independently of the first slicer group.
Use Independent Data Connections via Power Query
Import the same data multiple times using Get & Transform (Power Query) to establish separate data models without manually creating duplicate ranges in the sheet.
Master PivotTables and Slicers with WPS Spreadsheet
WPS Spreadsheet offers robust, user-friendly tools for complex data analysis, including full support for PivotTables and Slicers. You can easily manage report connections and create independent data views without the hassle of navigating overly complex menus.
- 1. Open your dataset in WPS Spreadsheet: Launch WPS Office and open your existing .xlsx file containing the raw data and PivotTables.
- 2. Insert your PivotTables: Navigate to the Insert tab, click PivotTable, and select your data ranges. You can define separate data names just like in Excel to isolate caches.
- 3. Insert Slicers: Click anywhere inside your PivotTable, navigate to the PivotTable Analyze tab (or Options tab), and click Insert Slicer to generate your interactive filters.
- 4. Manage Report Connections: Right-click the inserted Slicer, select 'Report Connections', and simply check or uncheck the PivotTables you want that specific slicer to control.
Frequently Asked Questions
Why do my slicers automatically control all PivotTables on the sheet?
When multiple PivotTables are created from the exact same data range, the software optimizes memory by using a single, shared PivotCache. Slicers are connected to the PivotCache, meaning any filter applied to the cache will inherently affect all linked PivotTables.
Can I simply disconnect a slicer from a specific PivotTable?
Yes, if the PivotTables share a cache. You can right-click the slicer, select 'Report Connections' (or 'PivotTable Connections'), and uncheck the boxes next to the specific PivotTables you do not want filtered. However, if you need a completely separate slicer for the exact same data, you need independent PivotCaches.
Does creating separate PivotCaches affect performance?
Yes. Creating multiple PivotCaches means the software stores the underlying dataset in memory multiple times. While this achieves slicer independence, it increases the overall file size and may cause performance lags on very large datasets.


