



How to Fix Extra Spaces When Exporting PDF Text to Excel or TXT

Question details
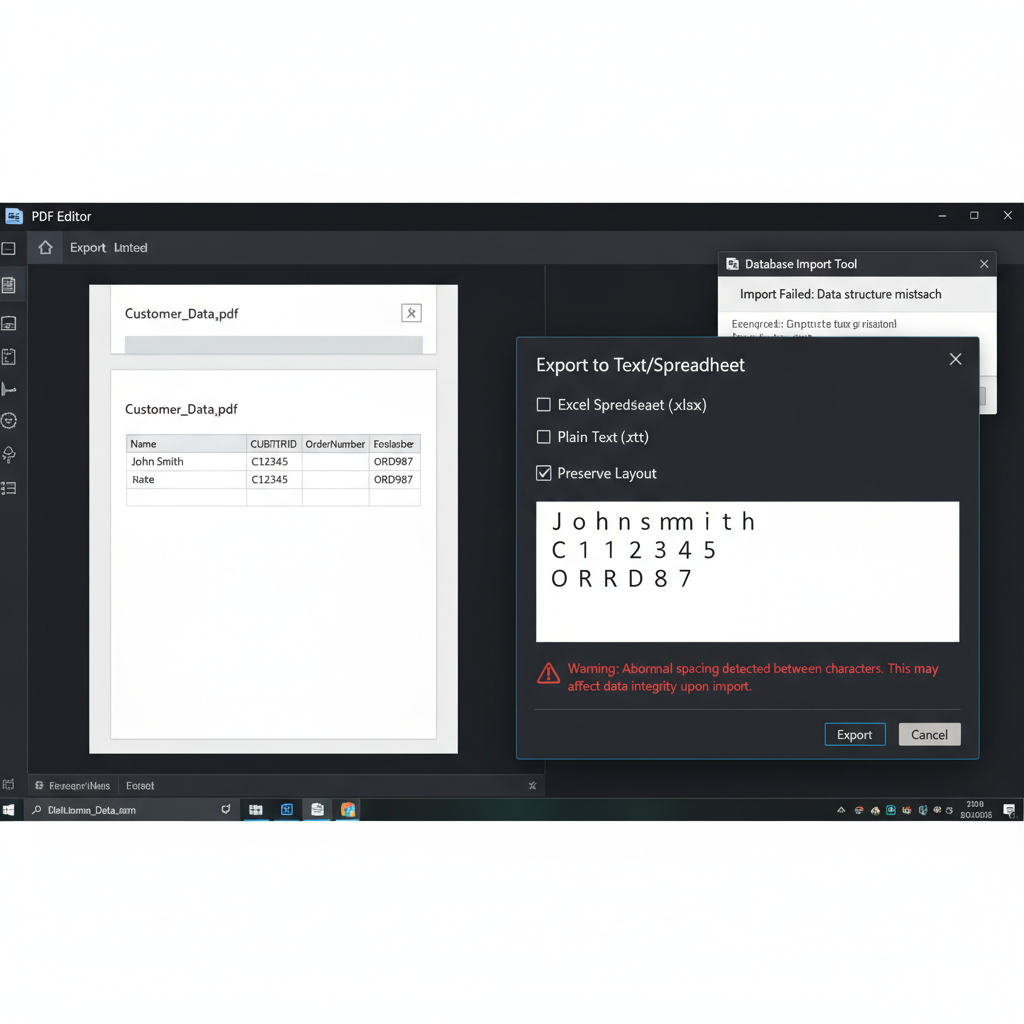
The user needs to resolve an issue where text exported from a PDF into an Excel spreadsheet or TXT file contains abnormal spaces between individual letters, which prevents the data from being imported into a database correctly.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Extracting text from a PDF document to Excel or a plain text file for the purpose of database importing.
- Observed behavior
- The exported text contains random, extra spaces between letters, disrupting the data structure and formatting.
Verify whether your PDF contains a standard text layer or if it is a scanned image, as PDFs with absolute text positioning or corrupted font encodings often require OCR to extract clean text.
Use OCR (Optical Character Recognition) to Re-extract the Text
Running an OCR process on the PDF bypasses the underlying font encoding errors by visually scanning and recognizing the text characters afresh.
Extra spaces often appear because the original PDF was created with software that places characters using exact visual coordinates rather than standard text spacing. Standard text extraction misinterprets these coordinate gaps as space characters.
Using OCR creates a brand new text layer based on the visual appearance of the words, which generally eliminates artificial spacing errors.
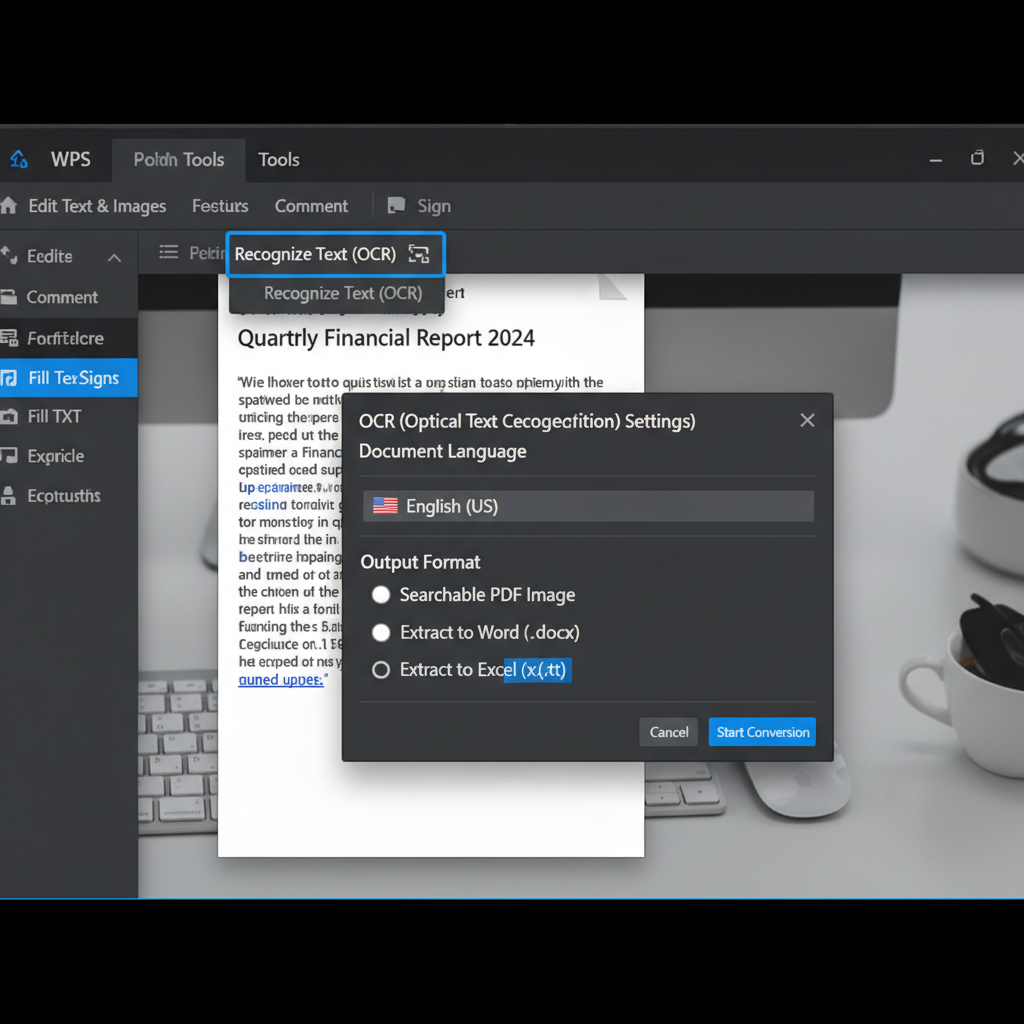
Launch your PDF software (such as WPS Office or Adobe Acrobat) and open the problematic PDF document.
Navigate to the 'Tools' menu and select the 'OCR' or 'Recognize Text' option. Ensure you set the document language correctly.
Choose 'Extract to Excel' or 'Extract to TXT' as your target output format within the OCR dialog box.
Click 'Convert' or 'Start' to process the document. Check the resulting file to ensure the extra spaces between letters have been resolved.
Clean Up the Extracted Data Directly in Excel
If you cannot re-export the PDF using OCR, you can fix the spacing issue on the already exported data using Excel's built-in cleanup tools.
Convert PDF to Excel Accurately with WPS Office
WPS Office features a robust PDF-to-Excel converter powered by advanced OCR technology. It seamlessly bypasses font encoding errors to give you perfectly formatted spreadsheets without extra spaces, ready for immediate database import.
- 1. Open PDF in WPS Office: Launch WPS Office, select 'PDF', and open the document you wish to extract data from.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and click the 'PDF to Excel' button.
- 3. Enable OCR Settings: In the conversion pop-up, check the 'OCR' box to ensure the software visually recognizes the text rather than relying on flawed PDF encoding.
- 4. Convert and Save: Click 'Convert'. Once finished, the clean Excel file will open automatically without the extra spaces.
Frequently Asked Questions
Why do PDFs add extra spaces between letters when exported?
This happens when the PDF is generated using specific print-to-PDF drivers that position characters using absolute coordinates instead of standard text wrapping, or when the document has a corrupted or non-standard font encoding.
What does a 'true text layer' mean in a PDF?
A true text layer contains embedded, encoded characters that software can seamlessly read and copy. If a PDF lacks this or the layer is corrupted, extraction tools read coordinate gaps as spaces, requiring OCR to fix.
Can I remove extra spaces in a TXT file without using Excel?
Yes. You can open the TXT file in a text editor like Notepad++, press 'Ctrl + H' to open Find and Replace, enter a single space in the 'Find what' field, leave 'Replace with' empty, and click 'Replace All'.
Will using OCR alter the table structure of my Excel file?
High-quality PDF editors are designed to reconstruct rows and columns based on visual lines and spacing. While minor adjustments might occasionally be necessary, OCR typically preserves the overall table structure well.


