



Why OCR Fails on Poor-Quality Cursive Text & How to Fix It
Question details
The user is trying to understand why an OCR engine fails to accurately extract text from a low-quality scan featuring a difficult cursive font.
- Product
- Device & OS
- not provided
- Scenario
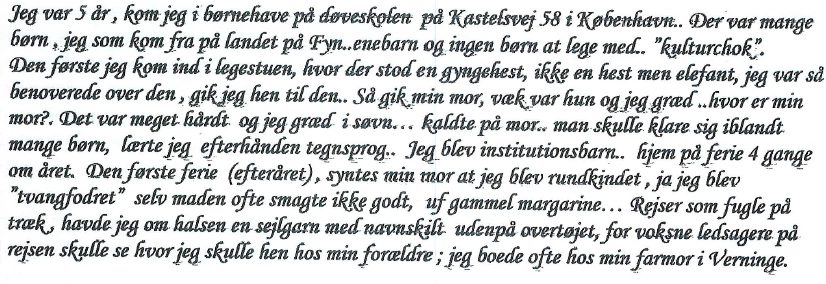
- Attempting to convert a low-resolution scanned document containing complex cursive fonts, such as Monotype Corsiva, into editable text.
- Observed behavior
- The OCR tool produces highly inaccurate text or completely fails to recognize the cursive characters.
Locate the original physical document if possible, as rescanning is often the only way to introduce enough detail for the OCR engine to read complex fonts.
Rescan the Document with Optimal Quality Settings
Improve the source image quality to give the OCR engine the best chance at recognizing connected cursive letters.
OCR engines rely heavily on crisp, distinct letterforms. Cursive fonts naturally blend letters, and poor scan resolution exacerbates this blending. Enlarging an already low-quality image will only magnify the blurriness without adding missing data.
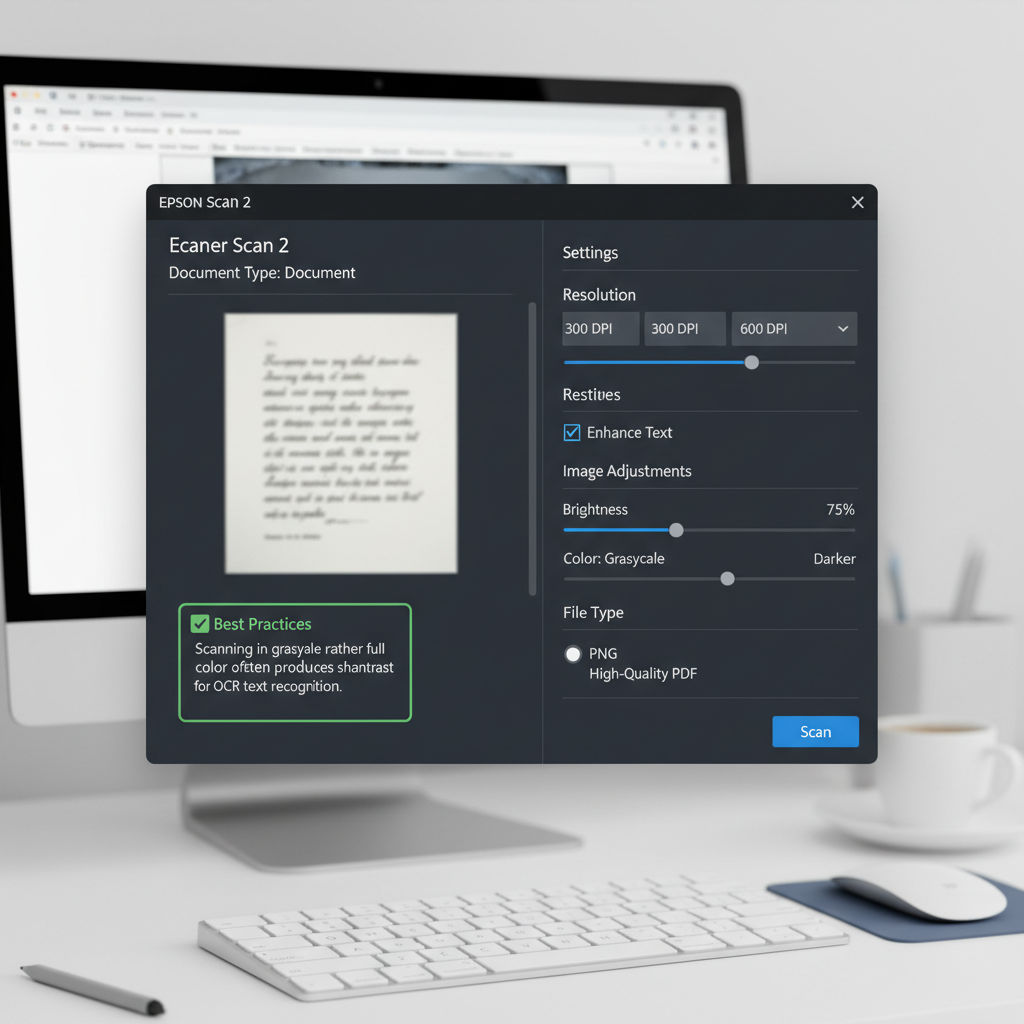
Set your scanner's resolution to at least 300 DPI (Dots Per Inch). For very intricate cursive fonts, opt for 600 DPI.
Enhance the contrast settings on your scanner software to ensure the dark cursive text stands out sharply against the white background.
Save the scanned file in a lossless image format like PNG or as a high-quality PDF before running it through your OCR software.
Manually Transcribe the Text
When the source document cannot be rescanned and the image is heavily degraded, manual transcription becomes the most reliable workaround.
Use WPS Office for Advanced OCR and PDF Conversion
WPS Office includes a built-in, highly accurate OCR engine designed to extract text from scanned documents efficiently. While extremely degraded cursive may still require manual review, WPS Office provides excellent, user-friendly tools to convert, edit, and format your PDFs seamlessly.
- 1. Open Your Scanned PDF: Launch WPS Office and open the scanned PDF document you wish to convert.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' or 'Picture to Text'.
- 3. Extract and Review: Select the target language and run the conversion. You can then review and manually correct any misidentified cursive letters directly in the editor.
Frequently Asked Questions
Why does OCR struggle with cursive fonts like Monotype Corsiva?
Cursive handwriting and specific script fonts connect letters together. OCR software looks for distinct, separated character shapes, making it difficult for the engine to determine where one cursive character ends and another begins. Poor scan quality further blurs these connections.
Will enlarging a blurry image improve OCR accuracy?
No. Enlarging a low-quality scan only scales up the existing pixels, making the image look pixelated or blocky. It does not add any new detail or sharpness to help the OCR engine read the text.
What is the best resolution for OCR text recognition?
For optimal OCR results, text documents should be scanned at a minimum of 300 DPI. For documents with very small text or complex cursive fonts, increasing the resolution to 600 DPI is highly recommended.


