



Fix Unrecognizable Characters When Converting PDF to Excel

Question details
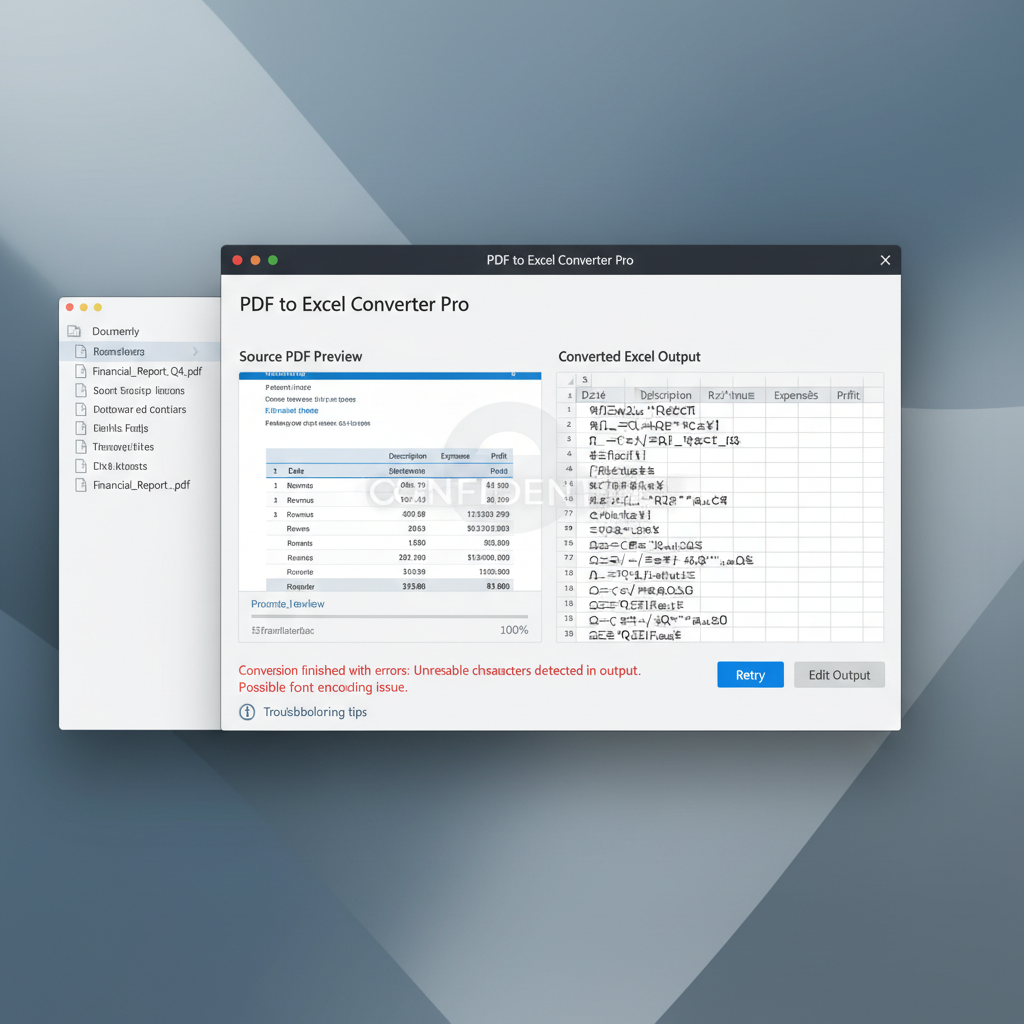
The user encounters unreadable or garbled characters in the resulting Excel spreadsheet after converting a PDF file.
- Product
- PDF to Excel Converter
- Device & OS
- not provided
- Scenario
- Converting a PDF document containing tables or data into an Excel spreadsheet for further editing and analysis.
- Observed behavior
- The exported Excel file displays unrecognizable, random, or gibberish characters instead of the original text, usually due to embedded font encoding issues or missing text layers.
Open your original PDF in a reader, highlight a paragraph of text, and copy-paste it into a plain text editor like Notepad to see if the text pastes correctly or as gibberish.
Use OCR for Scanned or Image-Based PDFs
Use this solution if you cannot select individual text in the PDF or if pasting copied text results in blank or garbled outputs.
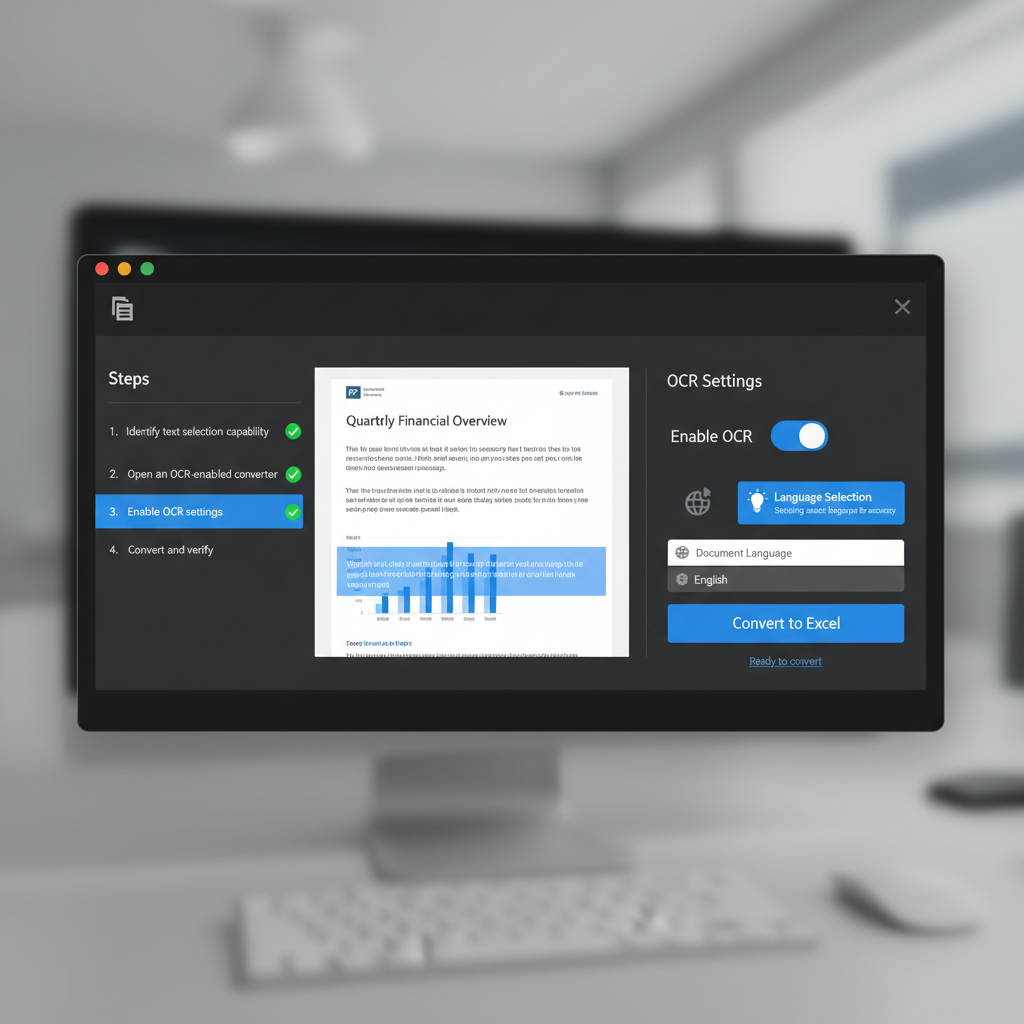
If the PDF was created from a scanner, it consists of images rather than editable text layers. Standard conversion tools may misinterpret the image patterns as unrecognizable characters. An Optical Character Recognition (OCR) tool is required to extract the text accurately.
Open the PDF document. Use your cursor to highlight a specific word. If the entire page highlights blue, it is a scanned document.
Launch a PDF to Excel converter that explicitly supports OCR (Optical Character Recognition) features.
Before initiating the conversion, toggle the 'Enable OCR' setting and select the correct document language to ensure high accuracy.
Click the convert button and open the newly generated Excel file to verify that the characters are now readable.
Re-Print the PDF to Rebuild Font Encoding
Use this method if the original text can be selected but pastes as gibberish, indicating a corrupted font character map.
Accurately Convert PDF to Excel with WPS Office
Bypass font encoding errors and scrambled characters by using the advanced PDF to Excel converter built into WPS Office. Equipped with high-precision OCR technology, it intelligently extracts table data and text accurately into perfectly formatted spreadsheets.
- 1. Open the PDF tool: Launch WPS Office and open your PDF document within the application.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' option.
- 3. Configure conversion settings: In the dialog box, ensure that OCR is checked if your document contains scanned pages, and set your desired output language.
- 4. Start conversion: Click 'Convert'. The accurately transcribed Excel file will automatically open in WPS Spreadsheet, ready for data analysis.
Frequently Asked Questions
Why do characters turn into gibberish when I copy text from a PDF?
This happens when the creator of the PDF used custom or subset fonts without embedding a proper character map (ToUnicode table). As a result, the computer knows how to display the shapes of the letters but does not know what actual letters they represent.
Can Adobe Acrobat fix PDF encoding errors automatically?
Not always. While Acrobat has built-in preflight tools to fix some document structures, deep encoding issues on custom fonts often require re-creating the PDF from the source file or using OCR technology to 'read' the text visually.
How do I know if my PDF requires OCR before converting?
Try highlighting individual words in the document. If you cannot highlight text, or if the selection box grabs the entire page as a single block, your PDF is an image-based scan. You will need a converter equipped with OCR to extract the data.
Will converting the file to Word first prevent the Excel formatting issue?
Usually no. If the root cause is a broken font character map or a scanned image, converting to Word will yield the same unrecognizable characters. The core text extraction process needs to be corrected first.


